
Model card: add 8-steps-dmd2-lora, refresh cats and PartiPrompts (Kromoss rows at update 11000)
Browse files- README.md +29 -19
- assets/cat-50steps-cfg3.webp +2 -2
- assets/cat-8steps-lora-dmd2.webp +3 -0
- assets/cat-8steps-lora.webp +0 -0
- assets/parti-comparison.webp +2 -2
README.md
CHANGED
|
@@ -17,12 +17,14 @@ Kromoss is a full fine-tune of [MOSS-Image-Base](https://huggingface.co/OpenMOSS
|
|
| 17 |
decoder) as [MOSS-Image-SFT](https://huggingface.co/OpenMOSS-Team/MOSS-Image-SFT), and this repo has the same
|
| 18 |
layout, so it is a drop-in replacement.
|
| 19 |
|
| 20 |
-
The repo also ships
|
| 21 |
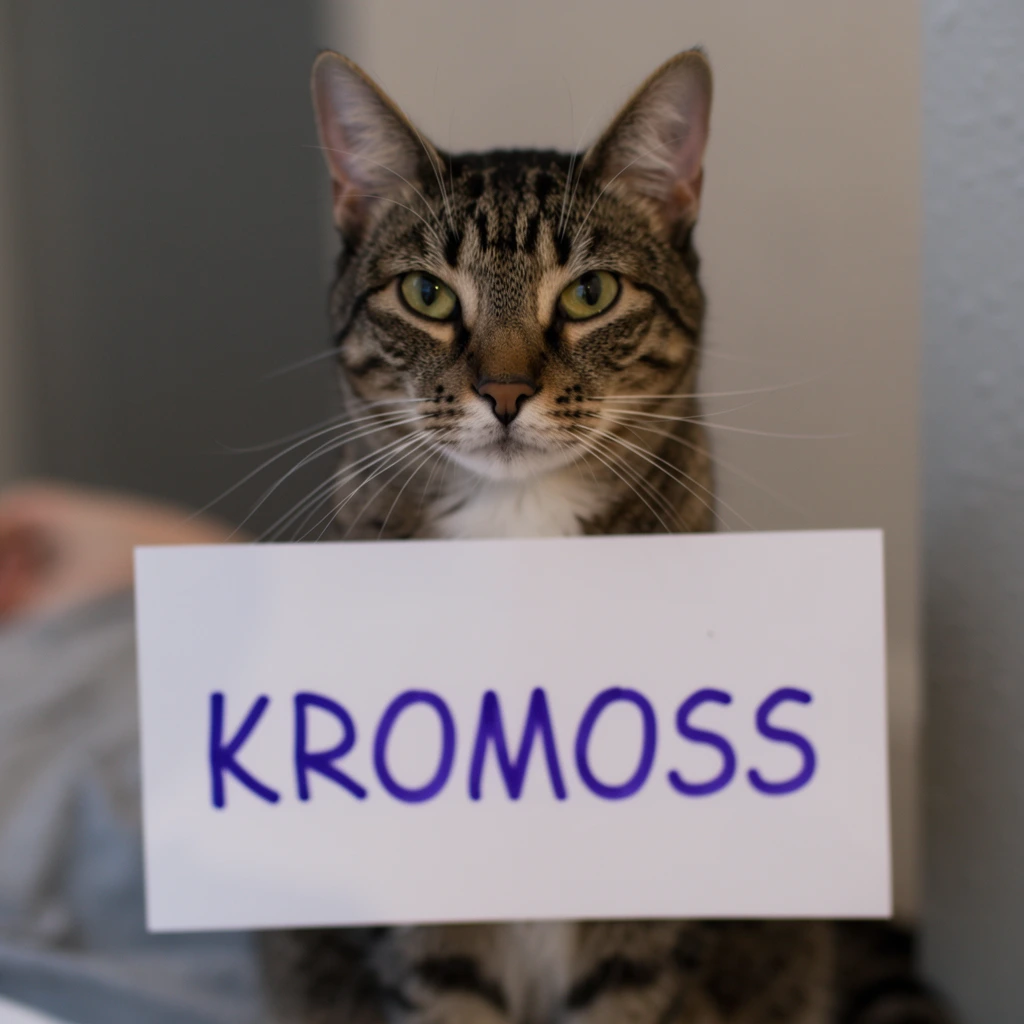
-
|
|
|
|
|
|
|
| 22 |
|
| 23 |
-
| 50 steps, CFG 3 | 8 steps, CFG 1 + `8-steps-dmd-lora` |
|
| 24 |
-
| --- | --- |
|
| 25 |
-
|  |  |
|
| 26 |
|
| 27 |
Checkpoint: update 11000 of the fine-tune (EMA weights), 704k training images.
|
| 28 |
|
|
@@ -70,11 +72,12 @@ Native ComfyUI support for MOSS-Image is in current ComfyUI master. The single f
|
|
| 70 |
| `diffusion_models/kromoss_int8_convrot.safetensors` | `models/diffusion_models/` | Load Diffusion Model (int8, 5.4 GB) |
|
| 71 |
| `text_encoders/qwen3.5_9b_bf16.safetensors` | `models/text_encoders/` | Load CLIP, type `moss_image` |
|
| 72 |
| `vae/flux2-vae_small.safetensors` | `models/vae/` | Load VAE |
|
|
|
|
| 73 |
| `8-steps-dmd-lora.safetensors` | `models/loras/` | LoraLoaderModelOnly, strength 1 |
|
| 74 |
|
| 75 |
`kromoss_bf16.safetensors` drops in for `moss_image_sft_bf16.safetensors` in the
|
| 76 |
-
Comfy-Org workflows (50 steps, CFG 3). With
|
| 77 |
-
ComfyUI maps the
|
| 78 |
|
| 79 |
`convert_to_comfy.py` converts any MOSS-Image diffusers `transformer/` folder (e.g. your own fine-tune) into this
|
| 80 |
single-file format (needs only `torch` and `safetensors`):
|
|
@@ -90,19 +93,24 @@ On MOSS-Image-SFT's `transformer/` it reproduces Comfy-Org's `moss_image_sft_bf1
|
|
| 90 |
The 168 block linears (`proj.{qkv,o,ffn_up_gate,ffn_down}`) are stored as int8 with per-row scales, after a
|
| 91 |
256-wide regular Hadamard rotation of the input dimension. ComfyUI rebuilds the rotation at load time and applies it
|
| 92 |
to the activations online, so no rotation matrices are stored. Each block also selects ComfyUI's int8 attention.
|
| 93 |
-
It drops in for the int8 Comfy-Org file and works with the
|
| 94 |
file; on `moss_image_sft_bf16.safetensors` it reproduces Comfy-Org's int8 file byte for byte:
|
| 95 |
|
| 96 |
```bash
|
| 97 |
python quantize_convrot.py my_model_bf16.safetensors my_model_int8_convrot.safetensors
|
| 98 |
```
|
| 99 |
|
| 100 |
-
## 8-step turbo
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 101 |
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
a LoRA loader at strength 1. With diffusers, apply it unmerged. Do not merge it into the bf16 weights: the
|
| 105 |
-
is close to bf16's rounding step.
|
| 106 |
|
| 107 |
```python
|
| 108 |
from safetensors.torch import load_file
|
|
@@ -118,14 +126,14 @@ def apply_lora(transformer, path, strength=1.0):
|
|
| 118 |
return out + (scale * (args[0].float() @ down.T) @ up.T).to(out.dtype)
|
| 119 |
modules[name].register_forward_hook(hook)
|
| 120 |
|
| 121 |
-
apply_lora(pipe.transformer, "8-steps-
|
| 122 |
image = pipe(prompt, height=1024, width=1024, num_inference_steps=8, guidance_scale=1.0,
|
| 123 |
generator=torch.Generator("cpu").manual_seed(42)).images[0]
|
| 124 |
```
|
| 125 |
|
| 126 |
## Sampling settings
|
| 127 |
|
| 128 |
-
| Setting | Full model | With
|
| 129 |
| --- | --- | --- |
|
| 130 |
| Sampler | Flow-matching Euler | Flow-matching Euler |
|
| 131 |
| Steps | 50 | 8 |
|
|
@@ -133,14 +141,16 @@ image = pipe(prompt, height=1024, width=1024, num_inference_steps=8, guidance_sc
|
|
| 133 |
| Shift | 5 | 5 |
|
| 134 |
| Layer skipping | Negative branch, layer index 22 | none (no negative branch) |
|
| 135 |
|
| 136 |
-
## PartiPrompts (100 prompts, CLIP ViT-L/14 score; Kromoss rows measured at update
|
| 137 |
|
| 138 |
| Model | CLIP |
|
| 139 |
| --- | --- |
|
| 140 |
| MOSS-Image-Base, 50 steps, CFG 3 | 27.19 |
|
| 141 |
-
| MOSS-Image-Base +
|
| 142 |
-
|
|
| 143 |
-
| Kromoss
|
|
|
|
|
|
|
| 144 |
|
| 145 |
Columns in the sheet below follow the table's order.
|
| 146 |
|
|
|
|
| 17 |
decoder) as [MOSS-Image-SFT](https://huggingface.co/OpenMOSS-Team/MOSS-Image-SFT), and this repo has the same
|
| 18 |
layout, so it is a drop-in replacement.
|
| 19 |
|
| 20 |
+
The repo also ships two 8-step turbo LoRAs distilled from MOSS-Image-Base: **8 steps, CFG 1**, no negative branch.
|
| 21 |
+
- `8-steps-dmd2-lora.safetensors` (recommended): the DMD LoRA below, further trained with DMD2's GAN stage against
|
| 22 |
+
real images. Slightly more contrast and detail, and the best PartiPrompts score.
|
| 23 |
+
- `8-steps-dmd-lora.safetensors`: data-space DMD distillation.
|
| 24 |
|
| 25 |
+
| 50 steps, CFG 3 | 8 steps, CFG 1 + `8-steps-dmd-lora` | 8 steps, CFG 1 + `8-steps-dmd2-lora` |
|
| 26 |
+
| --- | --- | --- |
|
| 27 |
+
|  |  |  |
|
| 28 |
|
| 29 |
Checkpoint: update 11000 of the fine-tune (EMA weights), 704k training images.
|
| 30 |
|
|
|
|
| 72 |
| `diffusion_models/kromoss_int8_convrot.safetensors` | `models/diffusion_models/` | Load Diffusion Model (int8, 5.4 GB) |
|
| 73 |
| `text_encoders/qwen3.5_9b_bf16.safetensors` | `models/text_encoders/` | Load CLIP, type `moss_image` |
|
| 74 |
| `vae/flux2-vae_small.safetensors` | `models/vae/` | Load VAE |
|
| 75 |
+
| `8-steps-dmd2-lora.safetensors` | `models/loras/` | LoraLoaderModelOnly, strength 1 |
|
| 76 |
| `8-steps-dmd-lora.safetensors` | `models/loras/` | LoraLoaderModelOnly, strength 1 |
|
| 77 |
|
| 78 |
`kromoss_bf16.safetensors` drops in for `moss_image_sft_bf16.safetensors` in the
|
| 79 |
+
Comfy-Org workflows (50 steps, CFG 3). With either LoRA, use KSampler with `euler` / `simple`, 8 steps, CFG 1.
|
| 80 |
+
ComfyUI maps the LoRAs' separate q/k/v onto the fused `qkv` slices.
|
| 81 |
|
| 82 |
`convert_to_comfy.py` converts any MOSS-Image diffusers `transformer/` folder (e.g. your own fine-tune) into this
|
| 83 |
single-file format (needs only `torch` and `safetensors`):
|
|
|
|
| 93 |
The 168 block linears (`proj.{qkv,o,ffn_up_gate,ffn_down}`) are stored as int8 with per-row scales, after a
|
| 94 |
256-wide regular Hadamard rotation of the input dimension. ComfyUI rebuilds the rotation at load time and applies it
|
| 95 |
to the activations online, so no rotation matrices are stored. Each block also selects ComfyUI's int8 attention.
|
| 96 |
+
It drops in for the int8 Comfy-Org file and works with the LoRAs. `quantize_convrot.py` makes it from a bf16 single
|
| 97 |
file; on `moss_image_sft_bf16.safetensors` it reproduces Comfy-Org's int8 file byte for byte:
|
| 98 |
|
| 99 |
```bash
|
| 100 |
python quantize_convrot.py my_model_bf16.safetensors my_model_int8_convrot.safetensors
|
| 101 |
```
|
| 102 |
|
| 103 |
+
## 8-step turbo LoRAs
|
| 104 |
+
|
| 105 |
+
Both were distilled from MOSS-Image-Base (50 steps, CFG 3) and transfer to Kromoss:
|
| 106 |
+
- `8-steps-dmd-lora.safetensors`: data-space DMD, 12000 updates.
|
| 107 |
+
- `8-steps-dmd2-lora.safetensors`: that run continued for 3000 updates with DMD2's second stage, a GAN
|
| 108 |
+
discriminator on the fake score trained against real images, at a quarter of the learning rate.
|
| 109 |
|
| 110 |
+
Both are fp32, rank 128 / alpha 128 on every block's `proj.{q,k,v,o,ffn_up_gate,ffn_down}`, with kohya keys
|
| 111 |
+
(`diffusion_model.<module>.lora_down.weight` / `lora_up.weight` / `alpha`). Use one at a time. In ComfyUI, load it
|
| 112 |
+
with a LoRA loader at strength 1. With diffusers, apply it unmerged. Do not merge it into the bf16 weights: the
|
| 113 |
+
delta is close to bf16's rounding step. 4 steps also works.
|
| 114 |
|
| 115 |
```python
|
| 116 |
from safetensors.torch import load_file
|
|
|
|
| 126 |
return out + (scale * (args[0].float() @ down.T) @ up.T).to(out.dtype)
|
| 127 |
modules[name].register_forward_hook(hook)
|
| 128 |
|
| 129 |
+
apply_lora(pipe.transformer, "8-steps-dmd2-lora.safetensors") # hf_hub_download("lodestones/Kromoss", ...)
|
| 130 |
image = pipe(prompt, height=1024, width=1024, num_inference_steps=8, guidance_scale=1.0,
|
| 131 |
generator=torch.Generator("cpu").manual_seed(42)).images[0]
|
| 132 |
```
|
| 133 |
|
| 134 |
## Sampling settings
|
| 135 |
|
| 136 |
+
| Setting | Full model | With either LoRA |
|
| 137 |
| --- | --- | --- |
|
| 138 |
| Sampler | Flow-matching Euler | Flow-matching Euler |
|
| 139 |
| Steps | 50 | 8 |
|
|
|
|
| 141 |
| Shift | 5 | 5 |
|
| 142 |
| Layer skipping | Negative branch, layer index 22 | none (no negative branch) |
|
| 143 |
|
| 144 |
+
## PartiPrompts (100 prompts, CLIP ViT-L/14 score; Kromoss rows measured at update 11000)
|
| 145 |
|
| 146 |
| Model | CLIP |
|
| 147 |
| --- | --- |
|
| 148 |
| MOSS-Image-Base, 50 steps, CFG 3 | 27.19 |
|
| 149 |
+
| MOSS-Image-Base + `8-steps-dmd-lora`, 8 steps, CFG 1 | 27.53 |
|
| 150 |
+
| MOSS-Image-Base + `8-steps-dmd2-lora`, 8 steps, CFG 1 | 27.59 |
|
| 151 |
+
| Kromoss, 50 steps, CFG 3 | 27.90 |
|
| 152 |
+
| Kromoss + `8-steps-dmd-lora`, 8 steps, CFG 1 | 27.99 |
|
| 153 |
+
| Kromoss + `8-steps-dmd2-lora`, 8 steps, CFG 1 | **28.13** |
|
| 154 |
|
| 155 |
Columns in the sheet below follow the table's order.
|
| 156 |
|
assets/cat-50steps-cfg3.webp
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
assets/cat-8steps-lora-dmd2.webp
ADDED

|
Git LFS Details
|
assets/cat-8steps-lora.webp
CHANGED
|

|
Git LFS Details
|
assets/parti-comparison.webp
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|