

MiniCPM-OCR
Collection
Fast, accurate OCR with correctness assessment. • 10 items • Updated • 17
MiniCPM-OCR 1.0 (1.3B) is the first OCR-specific model in the MiniCPM-V/o family. It focuses on text-centric document understanding — text, tables, formulas, charts, seals, and structured information extraction — and balances quality against speed on real-world captures.
Among the open-source OCR models compared, MiniCPM-OCR 1.0 reaches 1.2 pages/s and the highest equal-weight average score across OmniDocBench v1.6, Real5-OmniDocBench, Wild-OmniDocBench, and olmOCR-Bench.
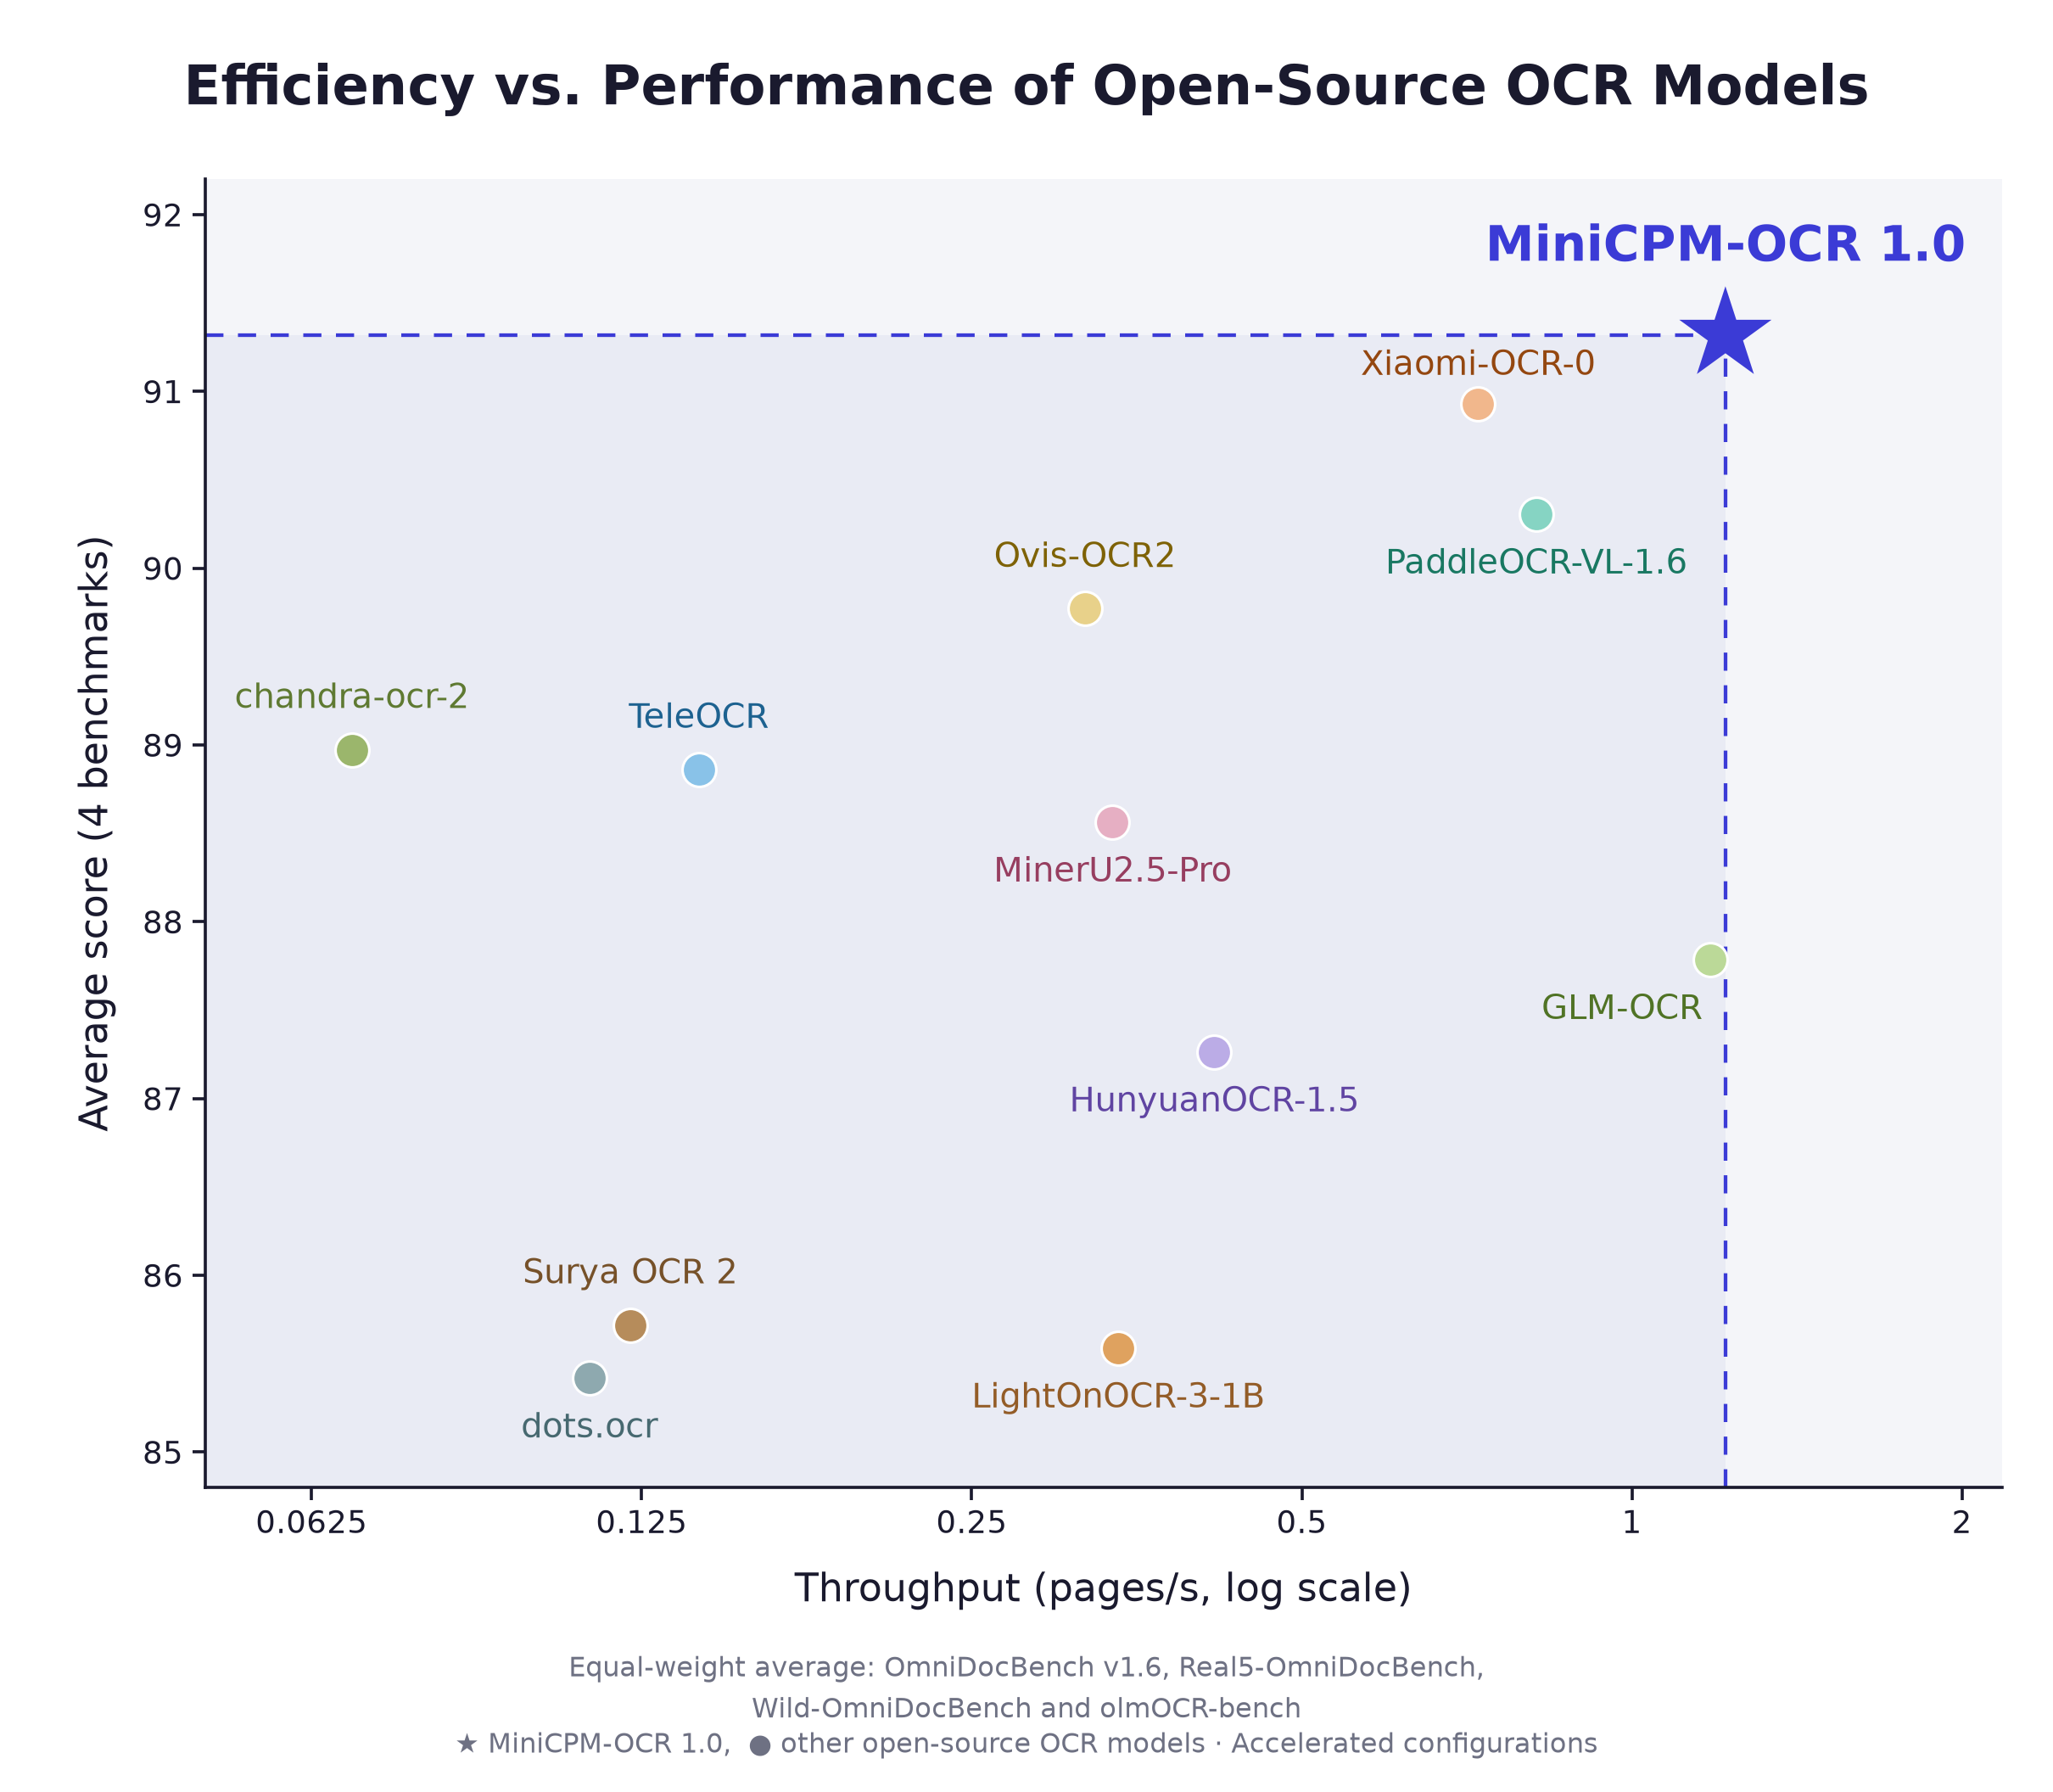
Average score is the equal-weight mean of the four benchmarks. All models use accelerated configurations. Settings and reproduction: reproduction guide. Per-model throughput: model guide.
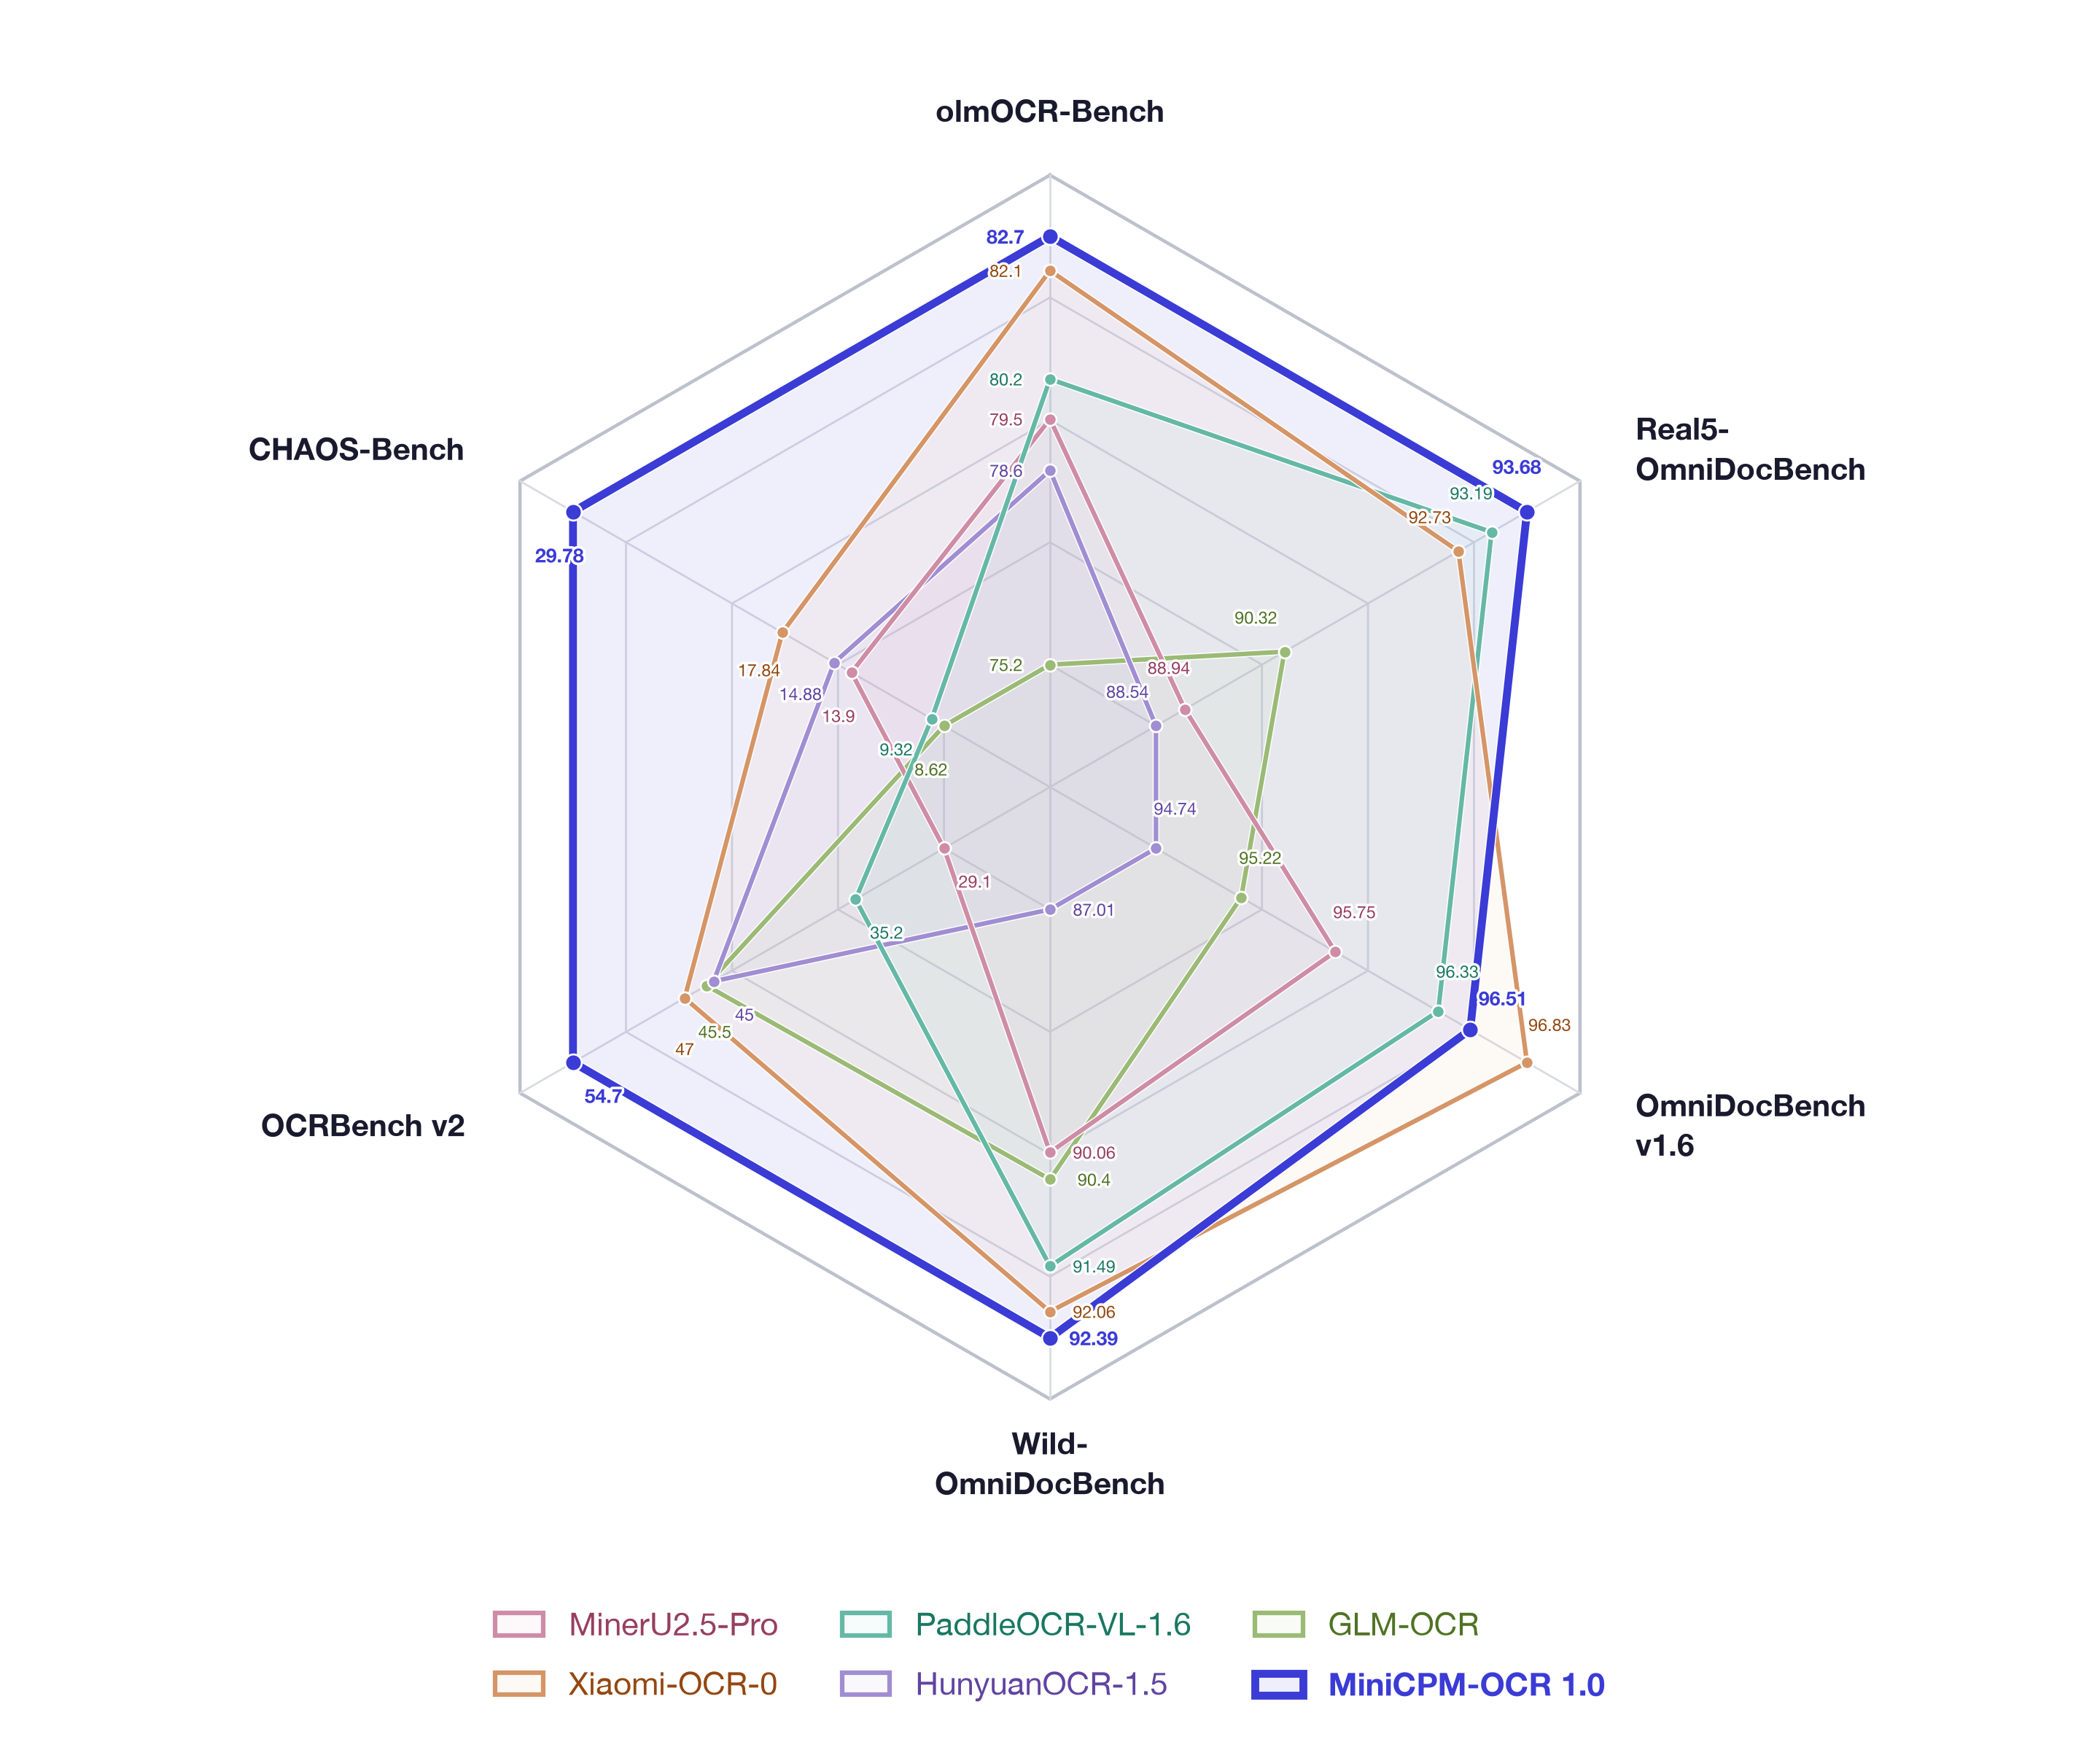
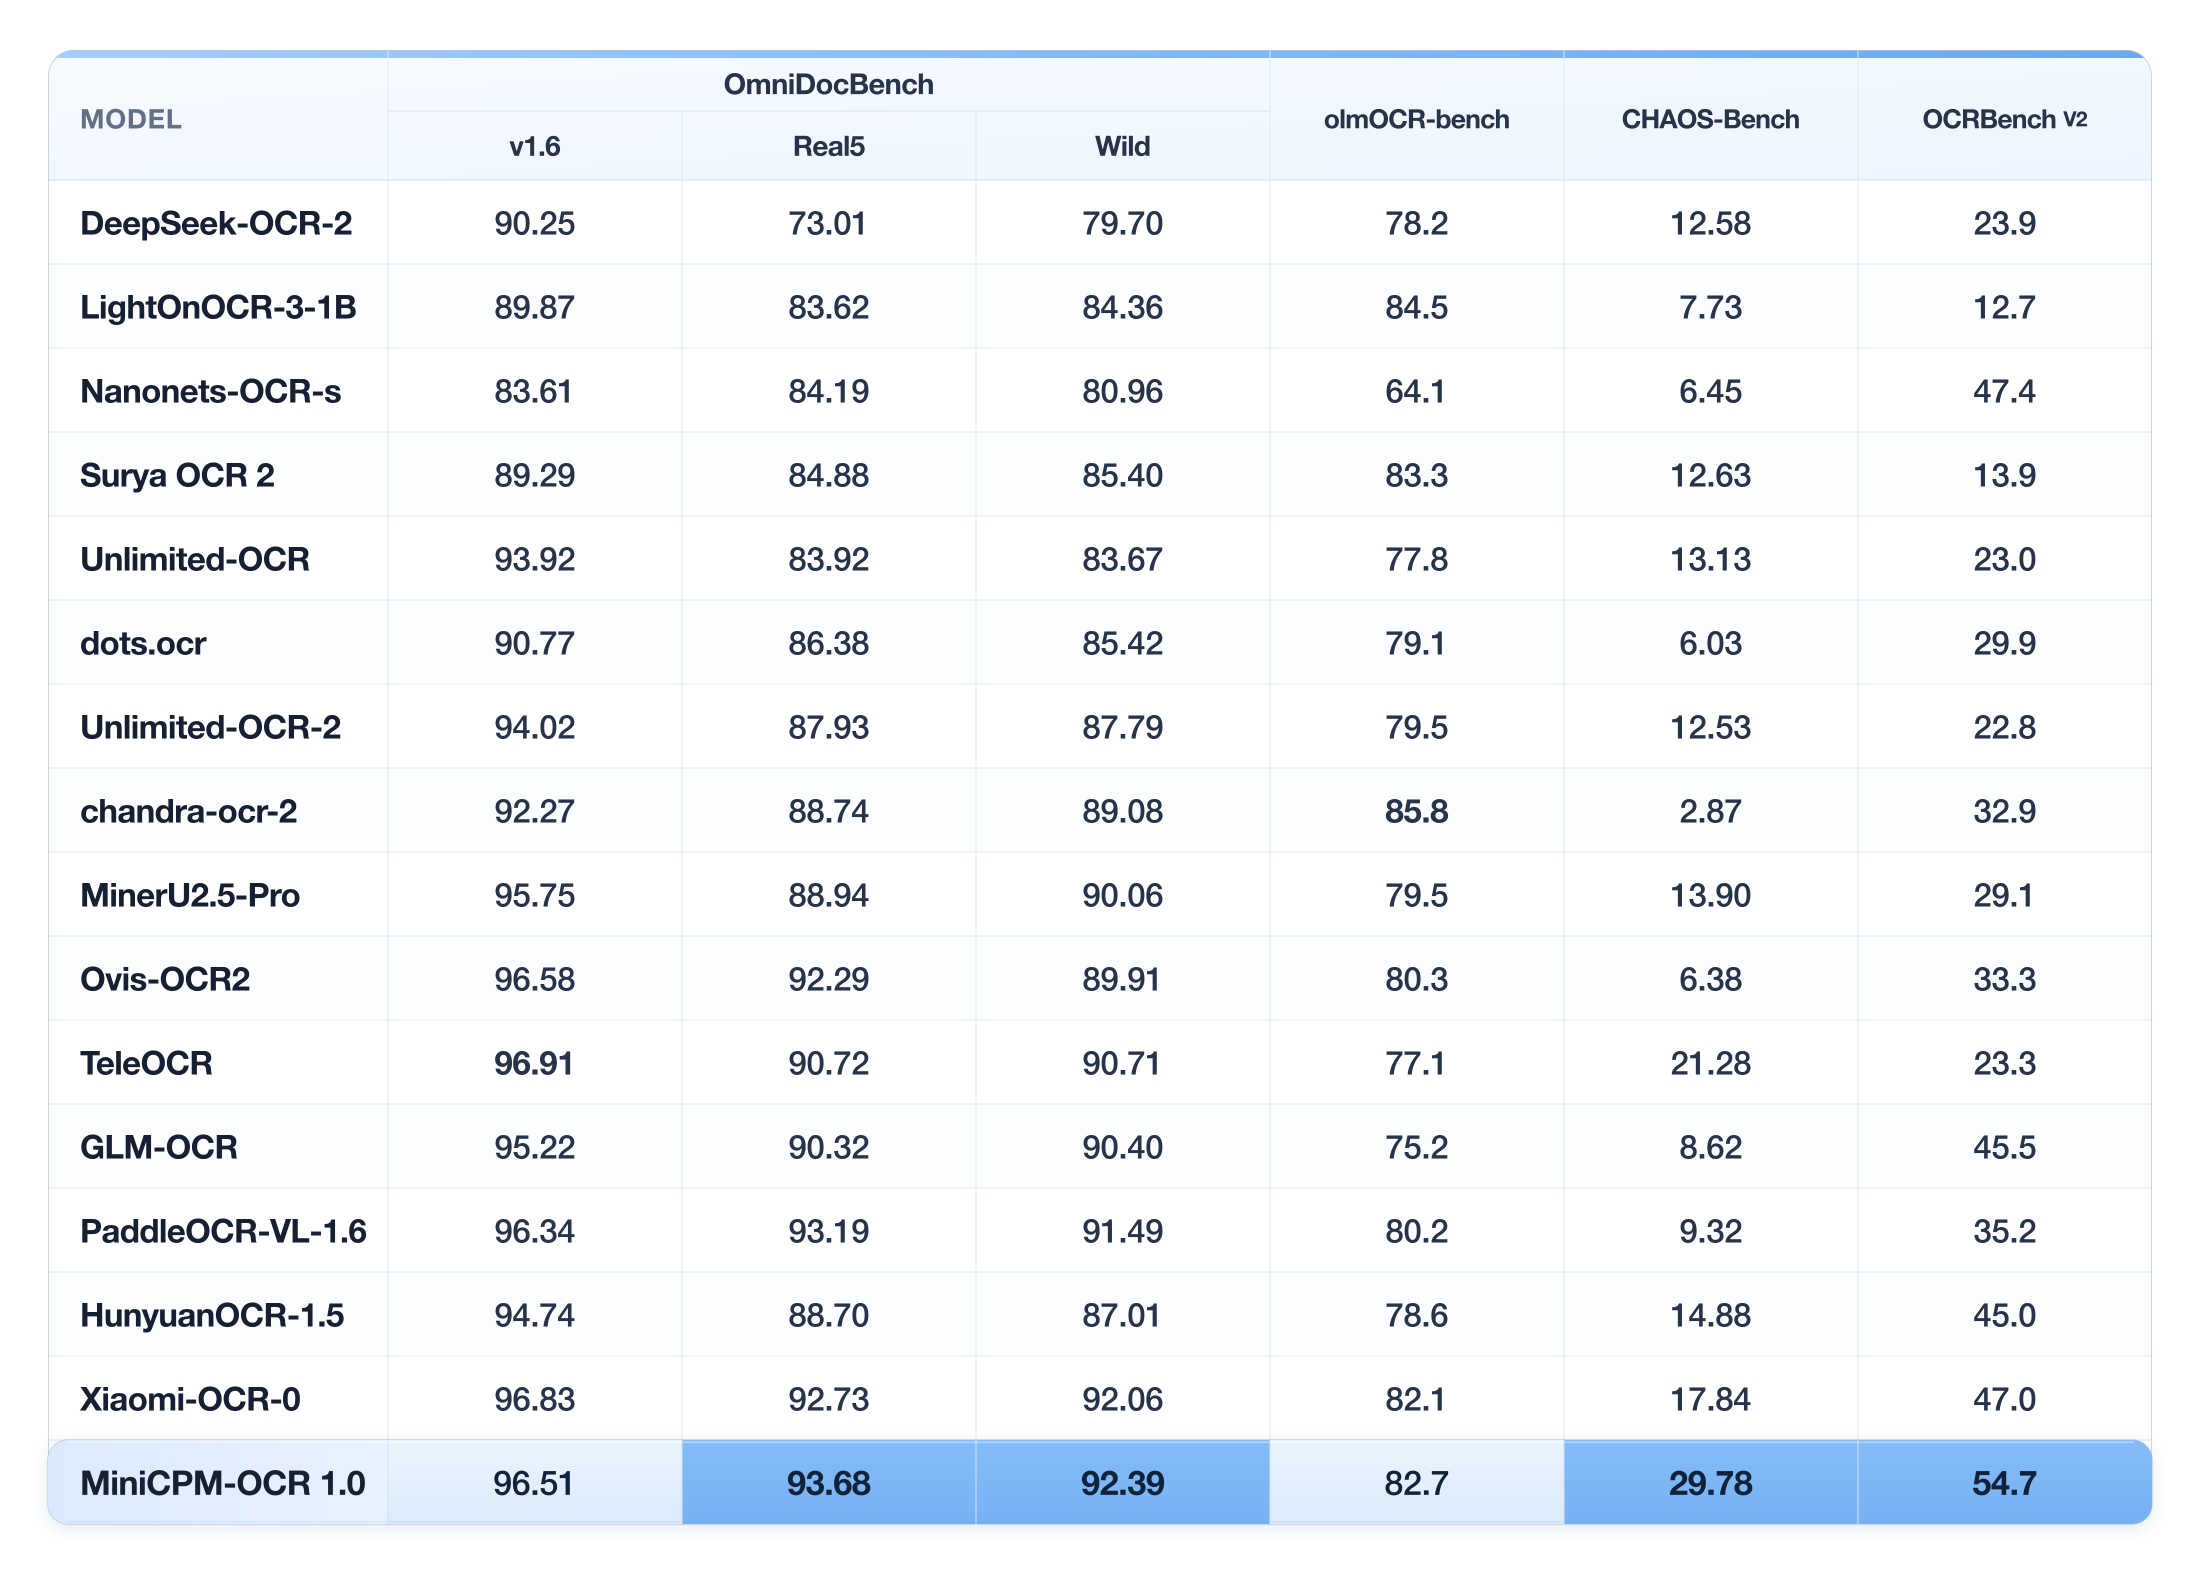
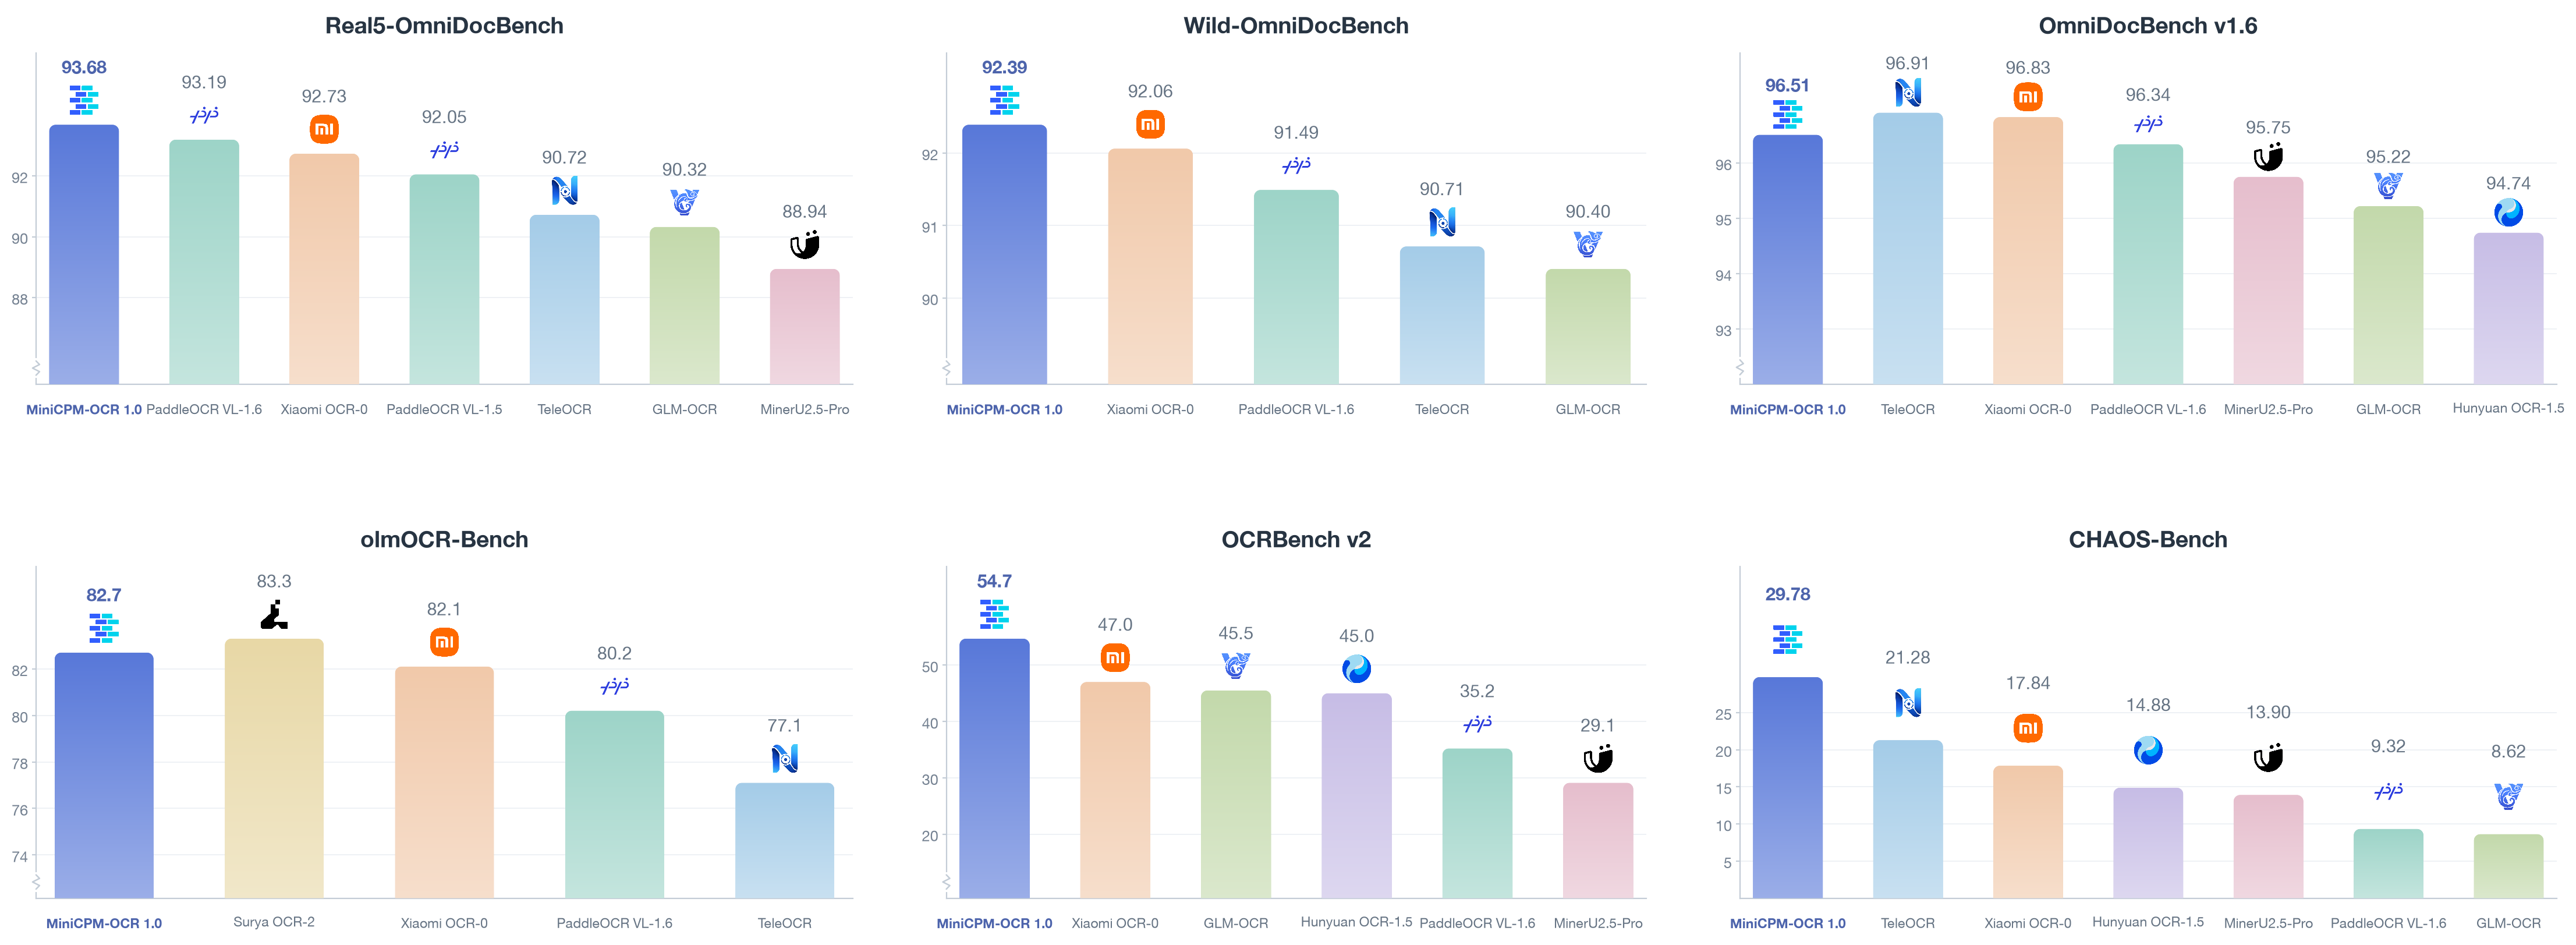
Each panel keeps its own benchmark's scores; higher is better. Scores from different benchmarks are not directly comparable. Test settings and reproduction steps are in the reproduction guide; per-benchmark discussion is in the model guide.
On an NVIDIA GeForce RTX 5090 with all 1651 OmniDocBench v1.6 images, image-level concurrency 1, and each system's accelerated configuration, MiniCPM-OCR 1.0 reaches 1.2 pages/s (relative throughput 1.00×; higher is faster).
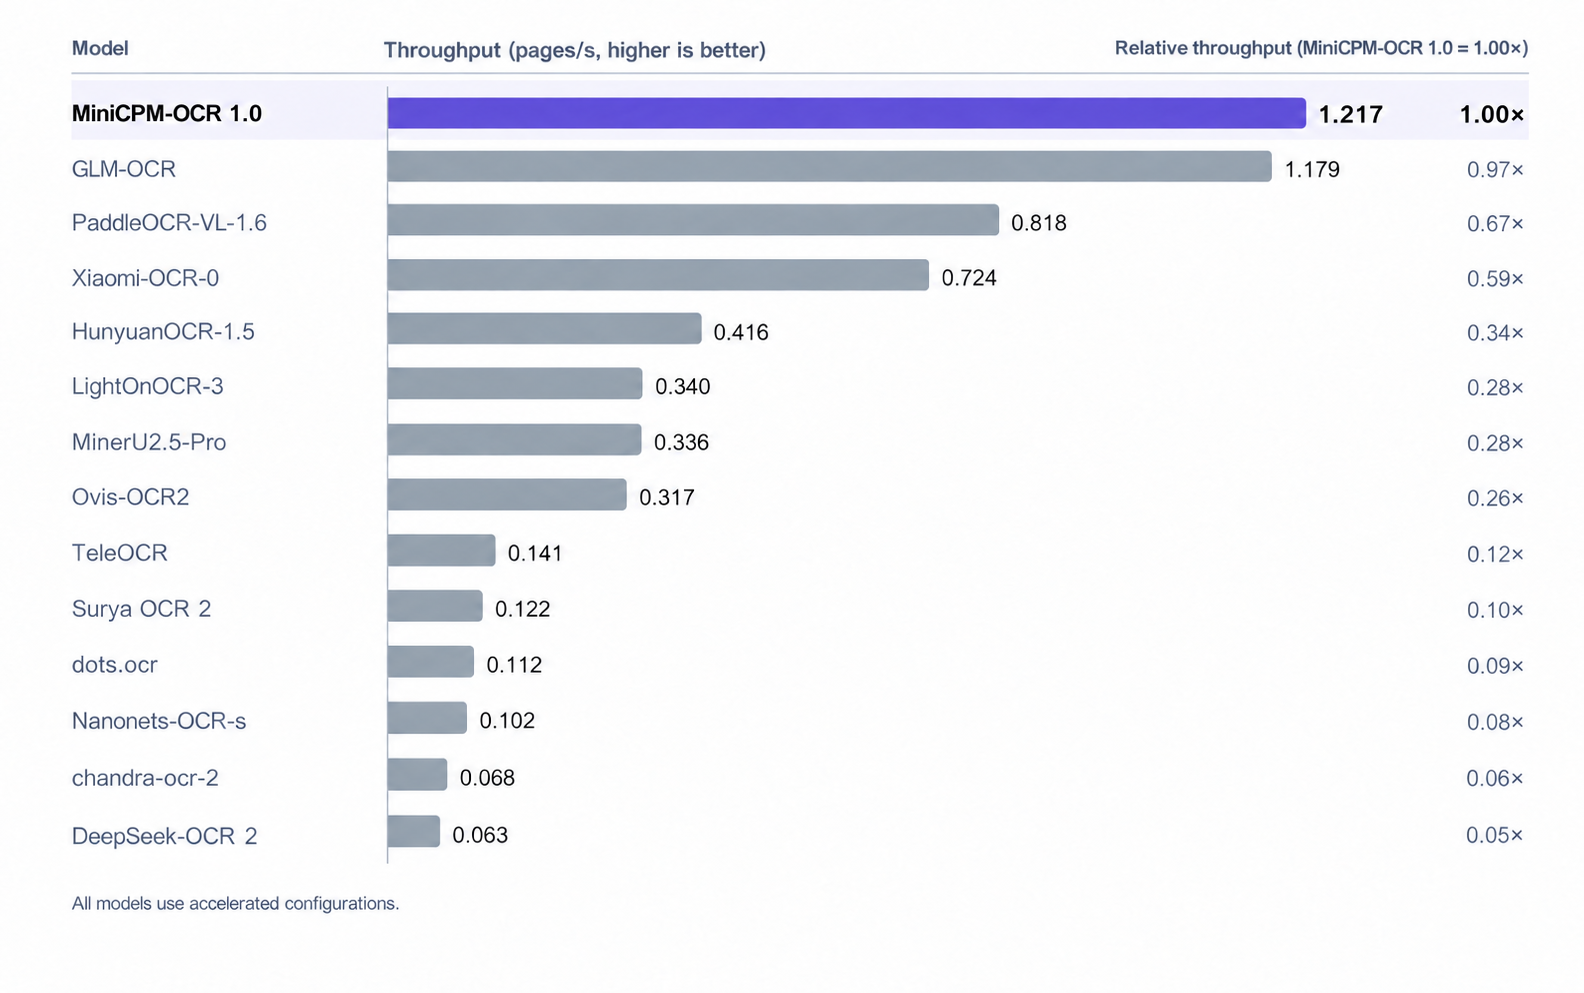
Concurrency 1 is image-level: regions inside a page are still recognised in parallel. Real throughput also depends on page content, backend, concurrency, and hardware.
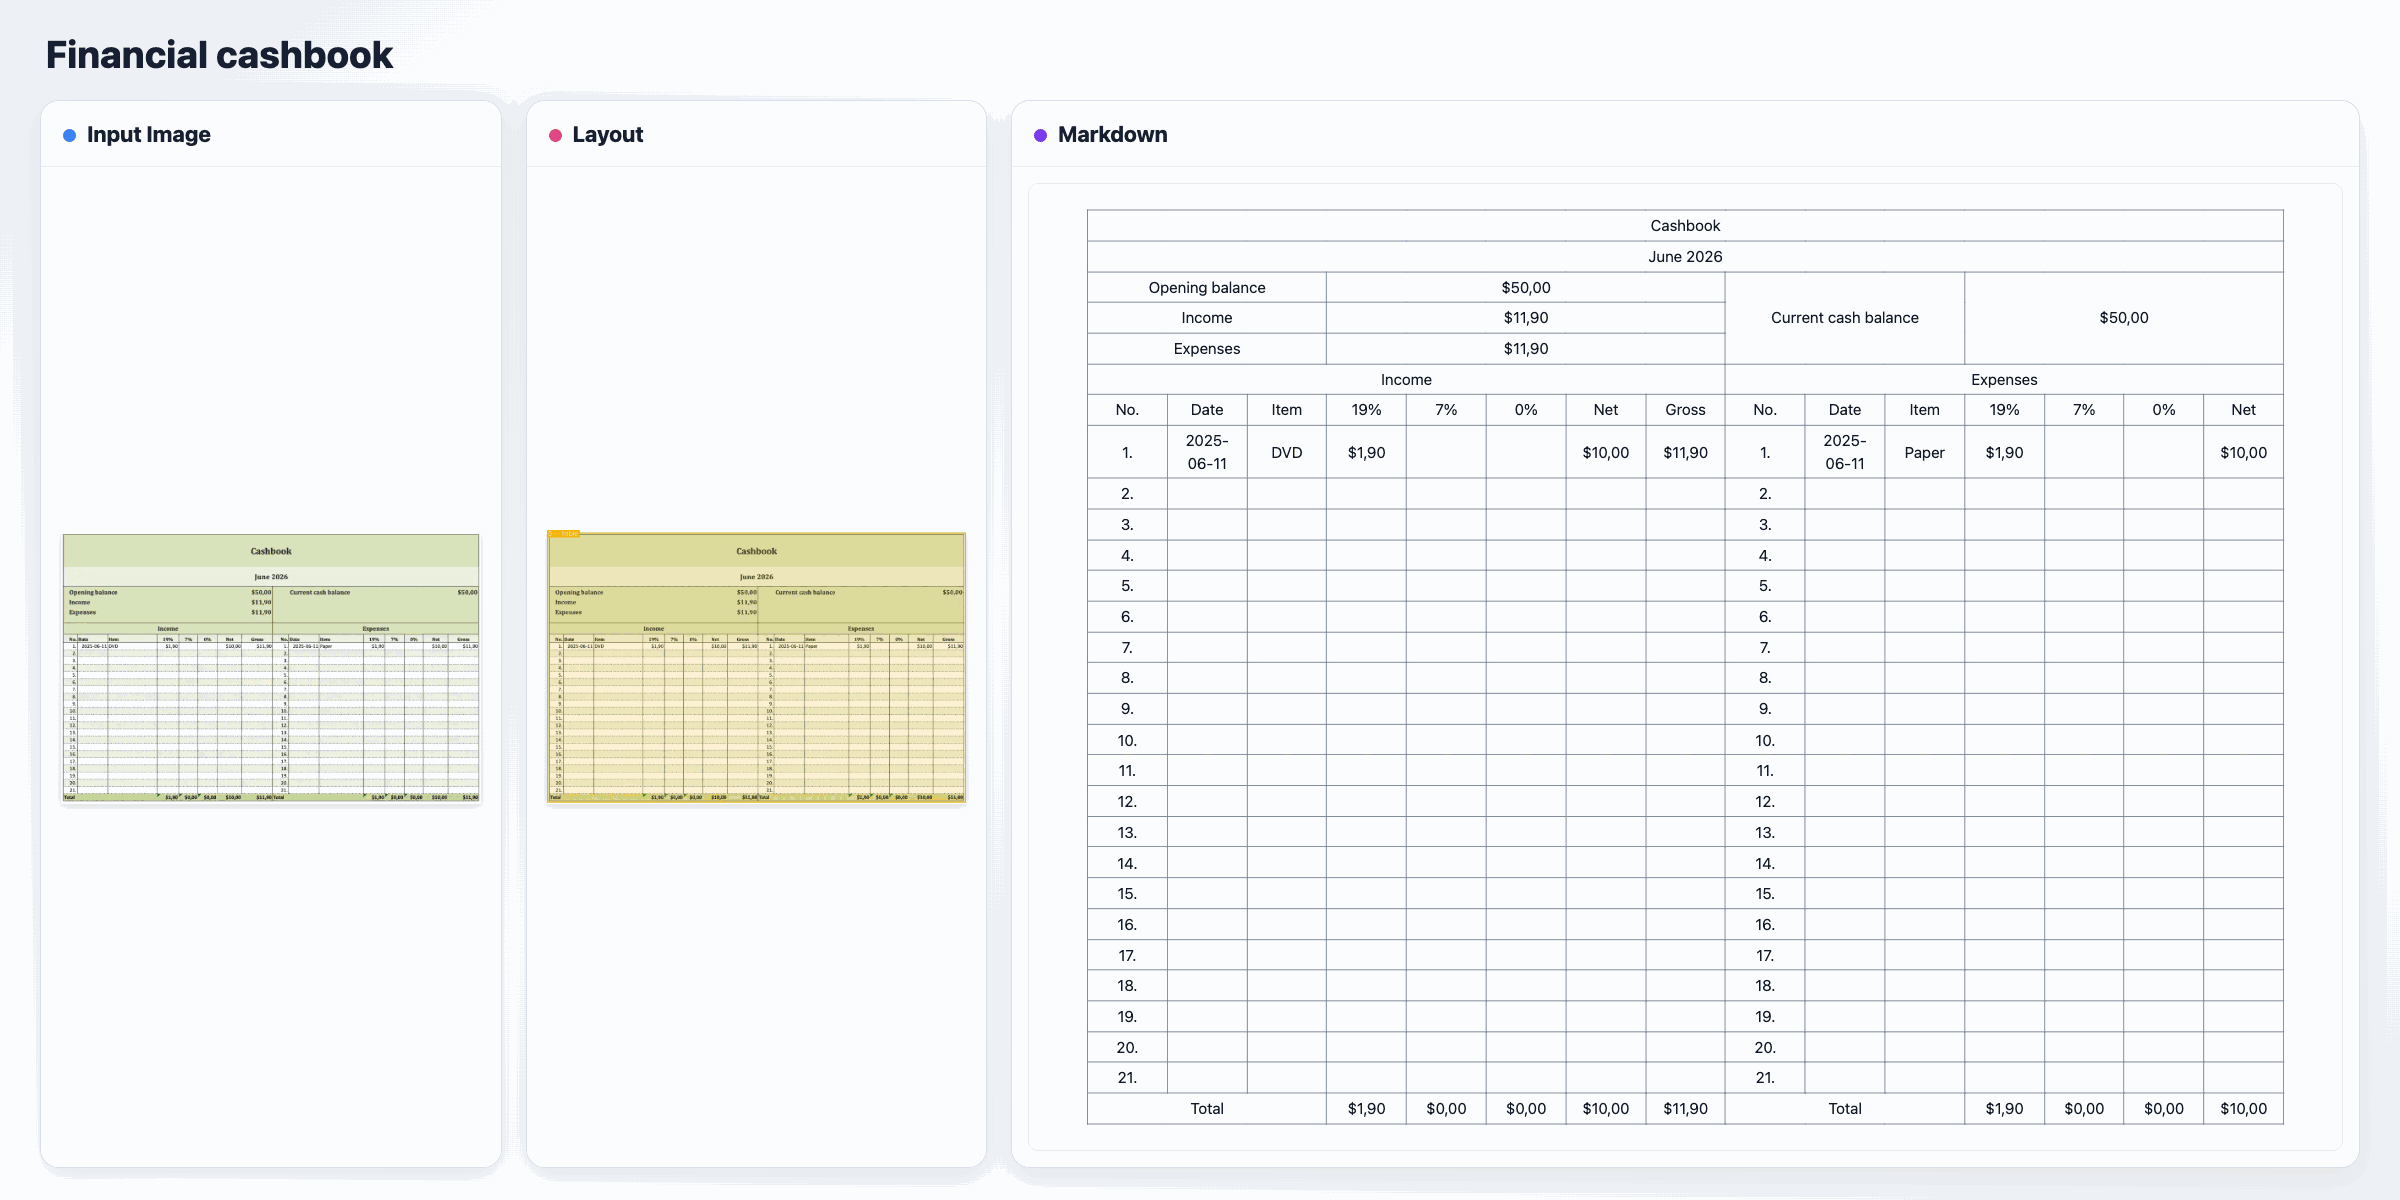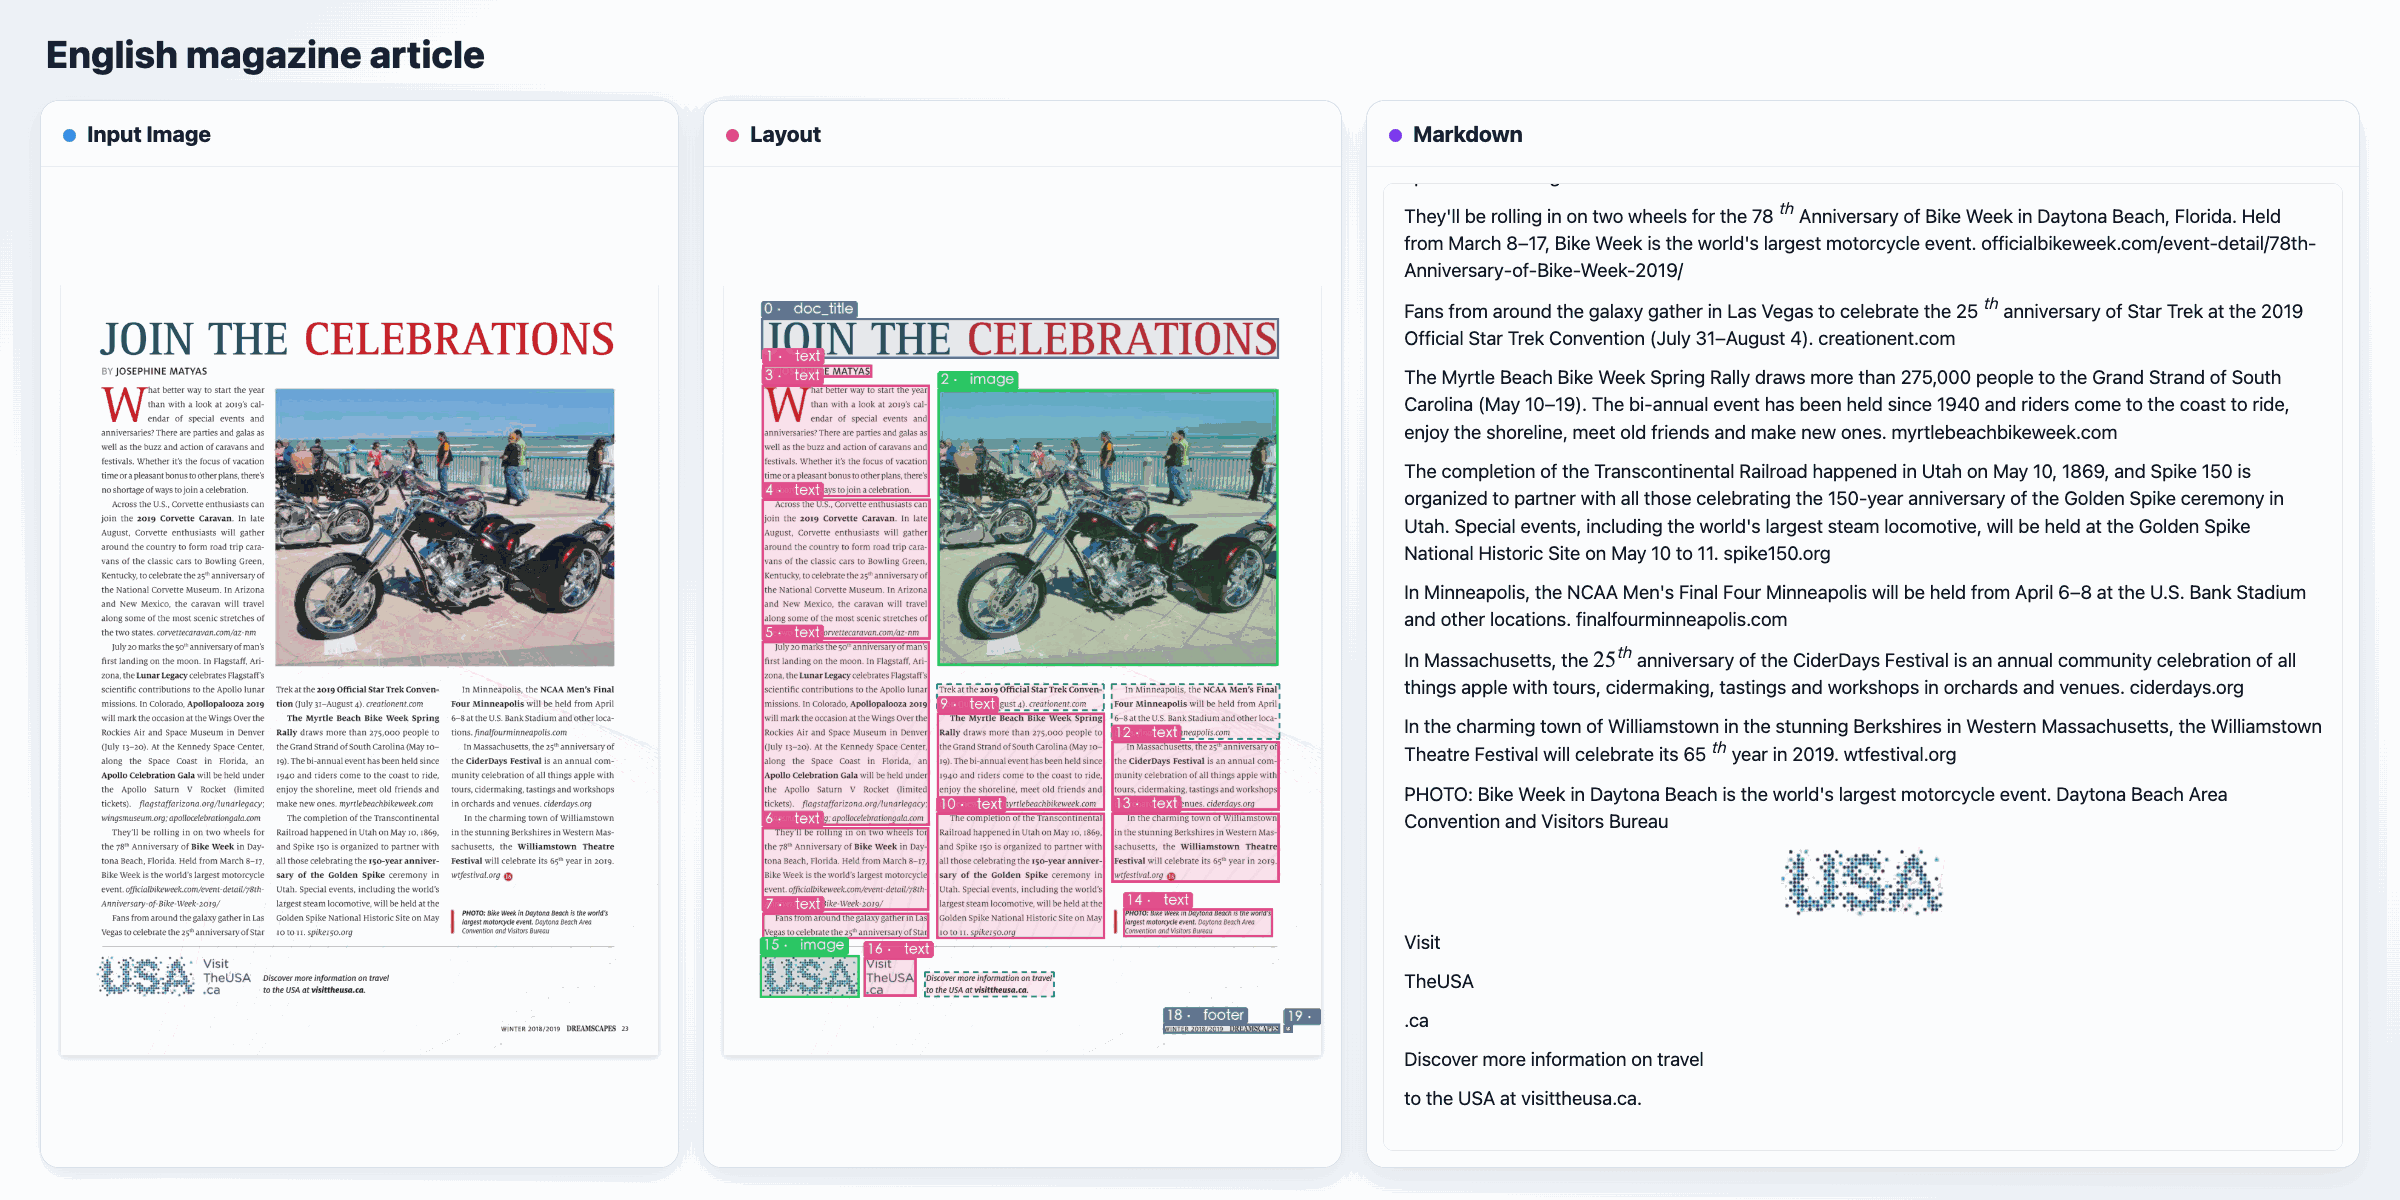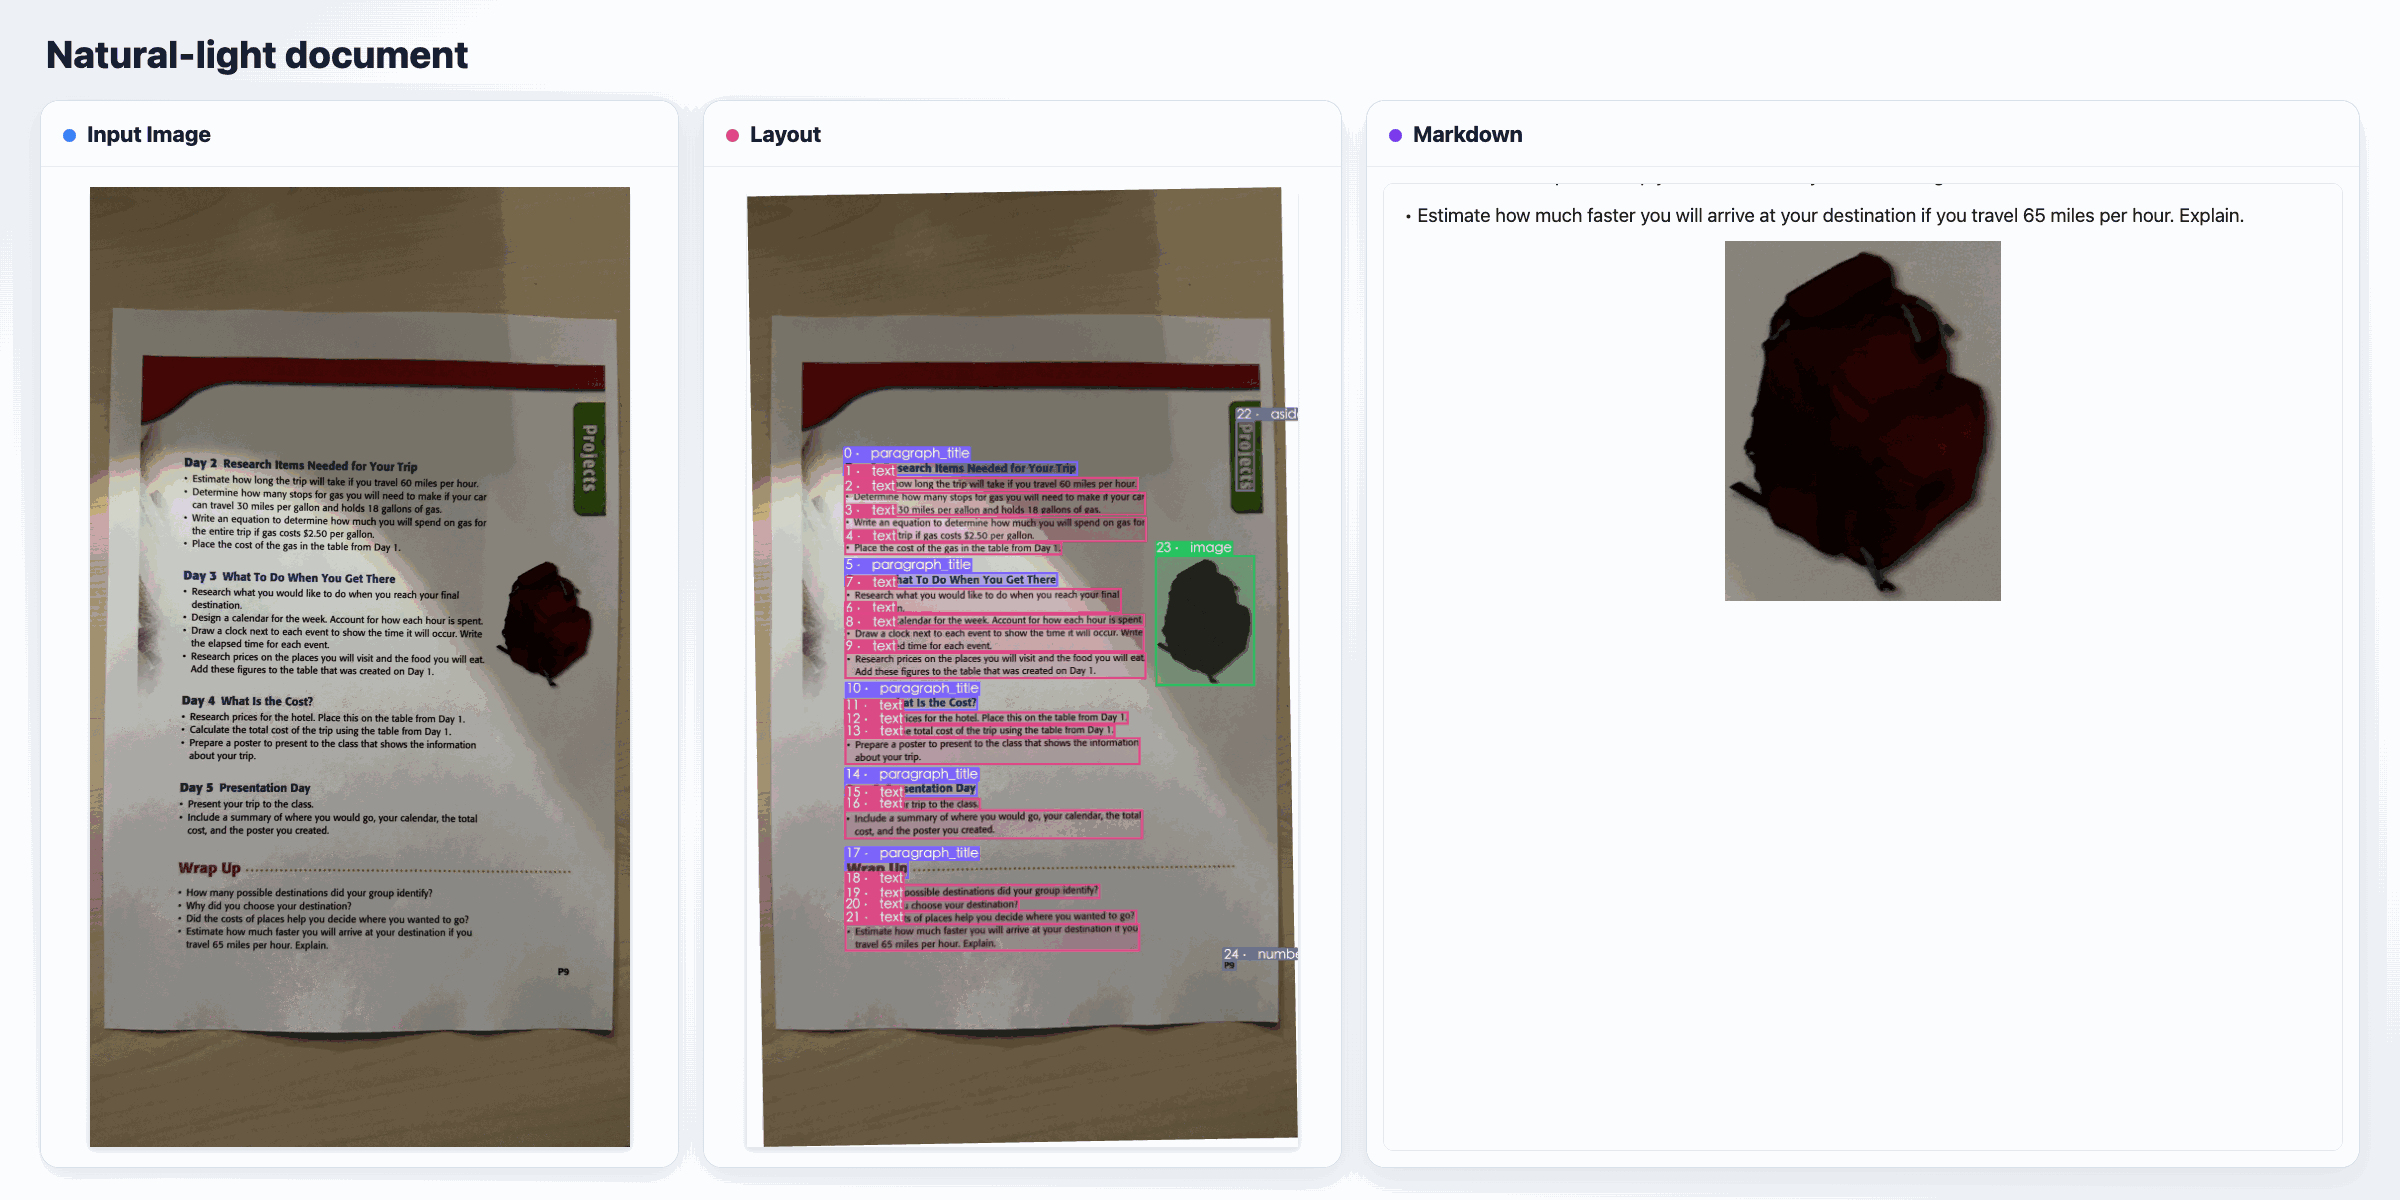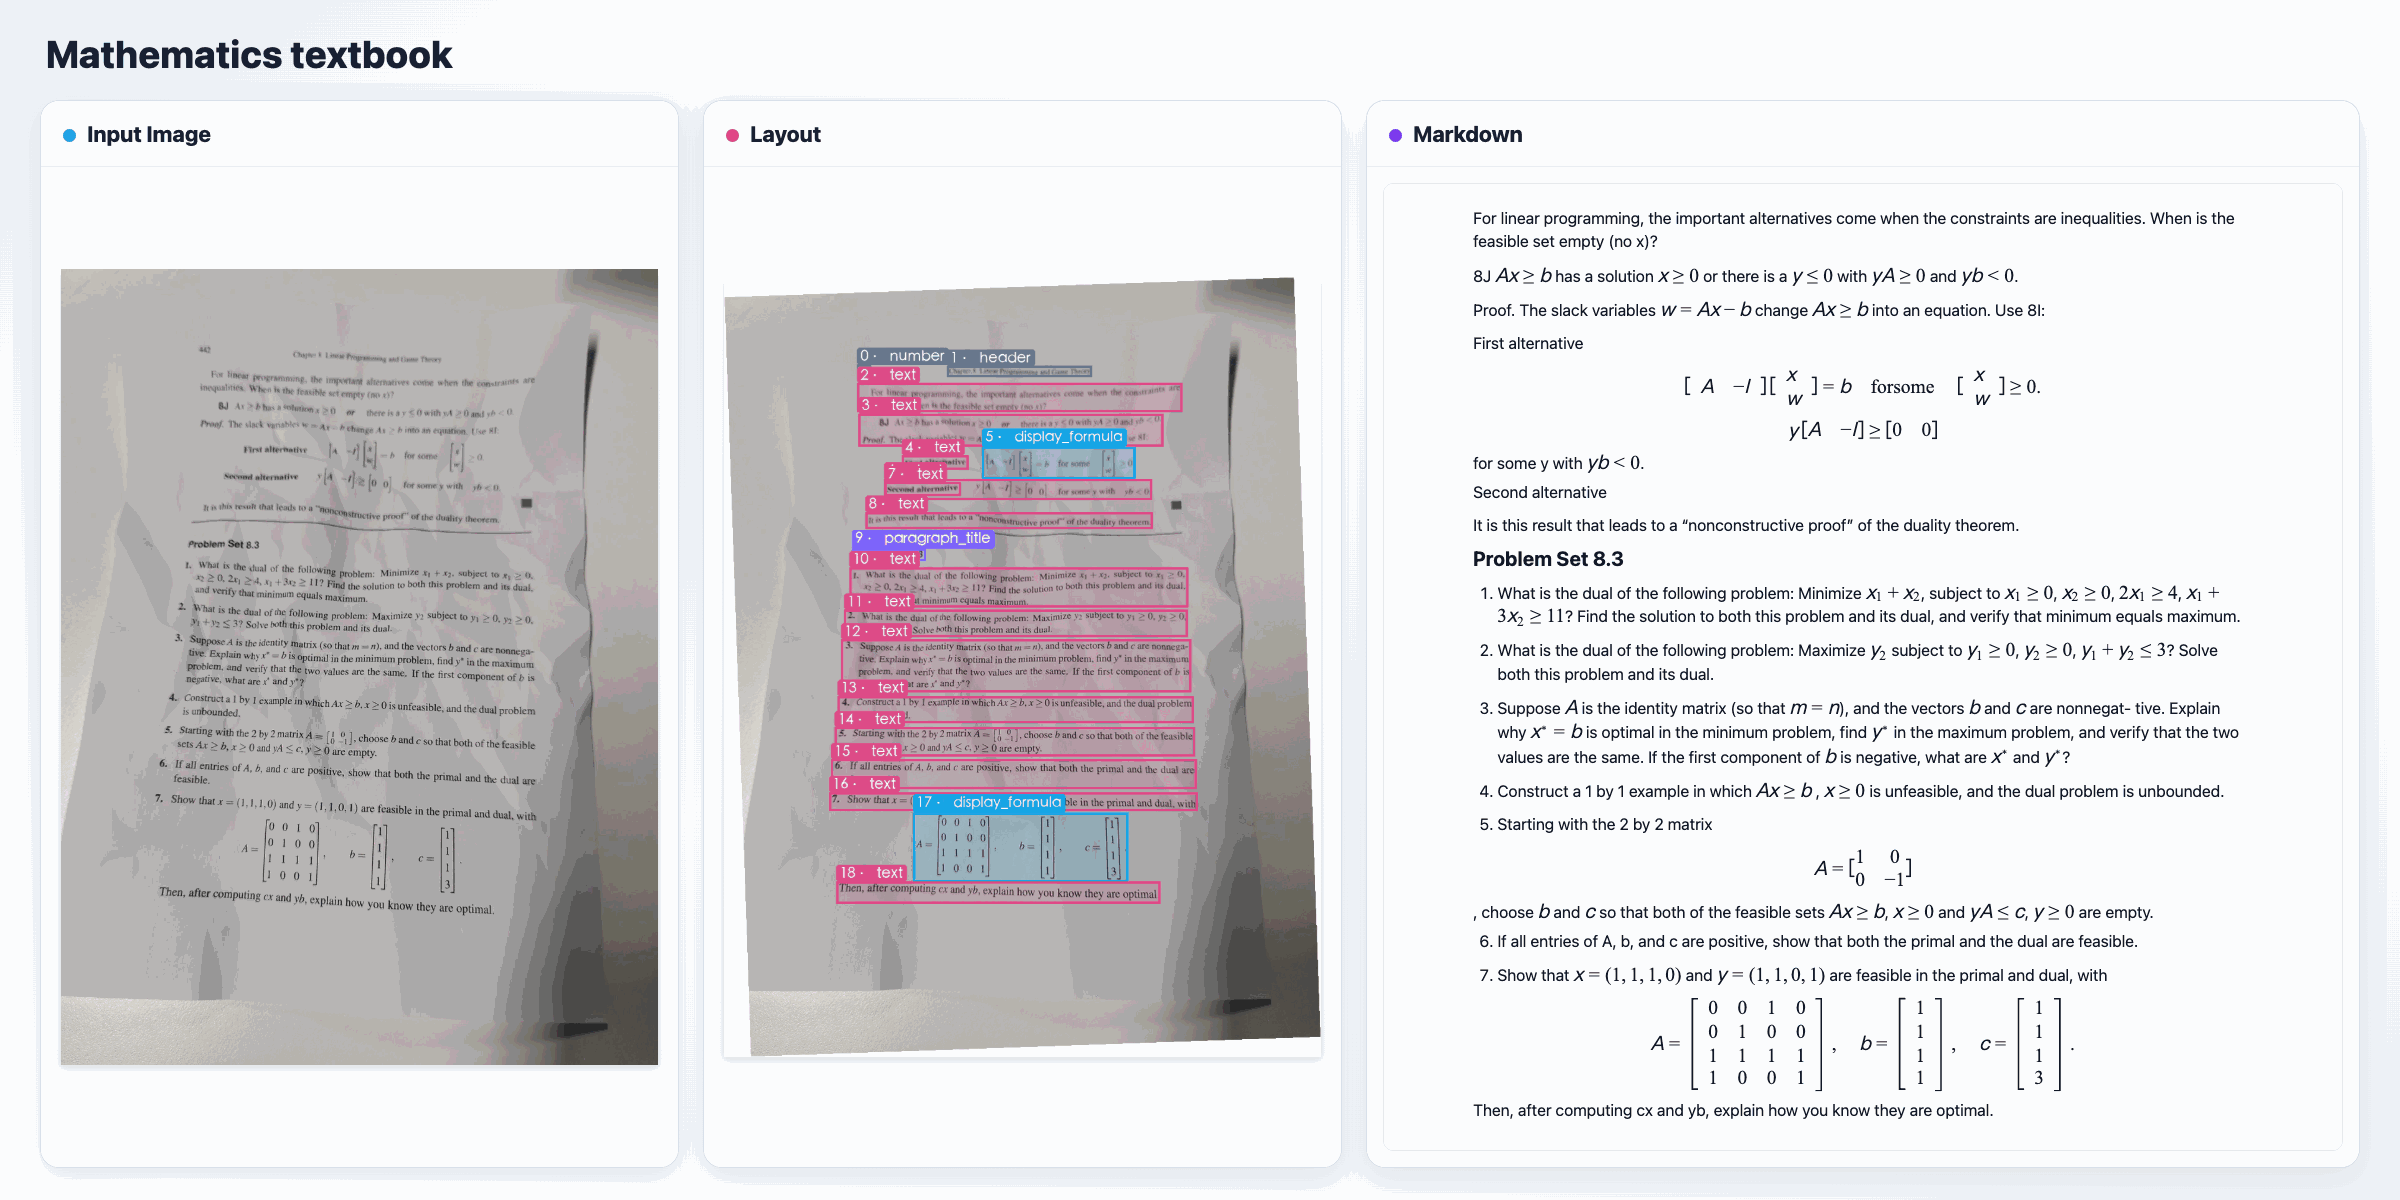
Left to right: original document, detected layout, and rendered Markdown.
English documents
Chinese documents
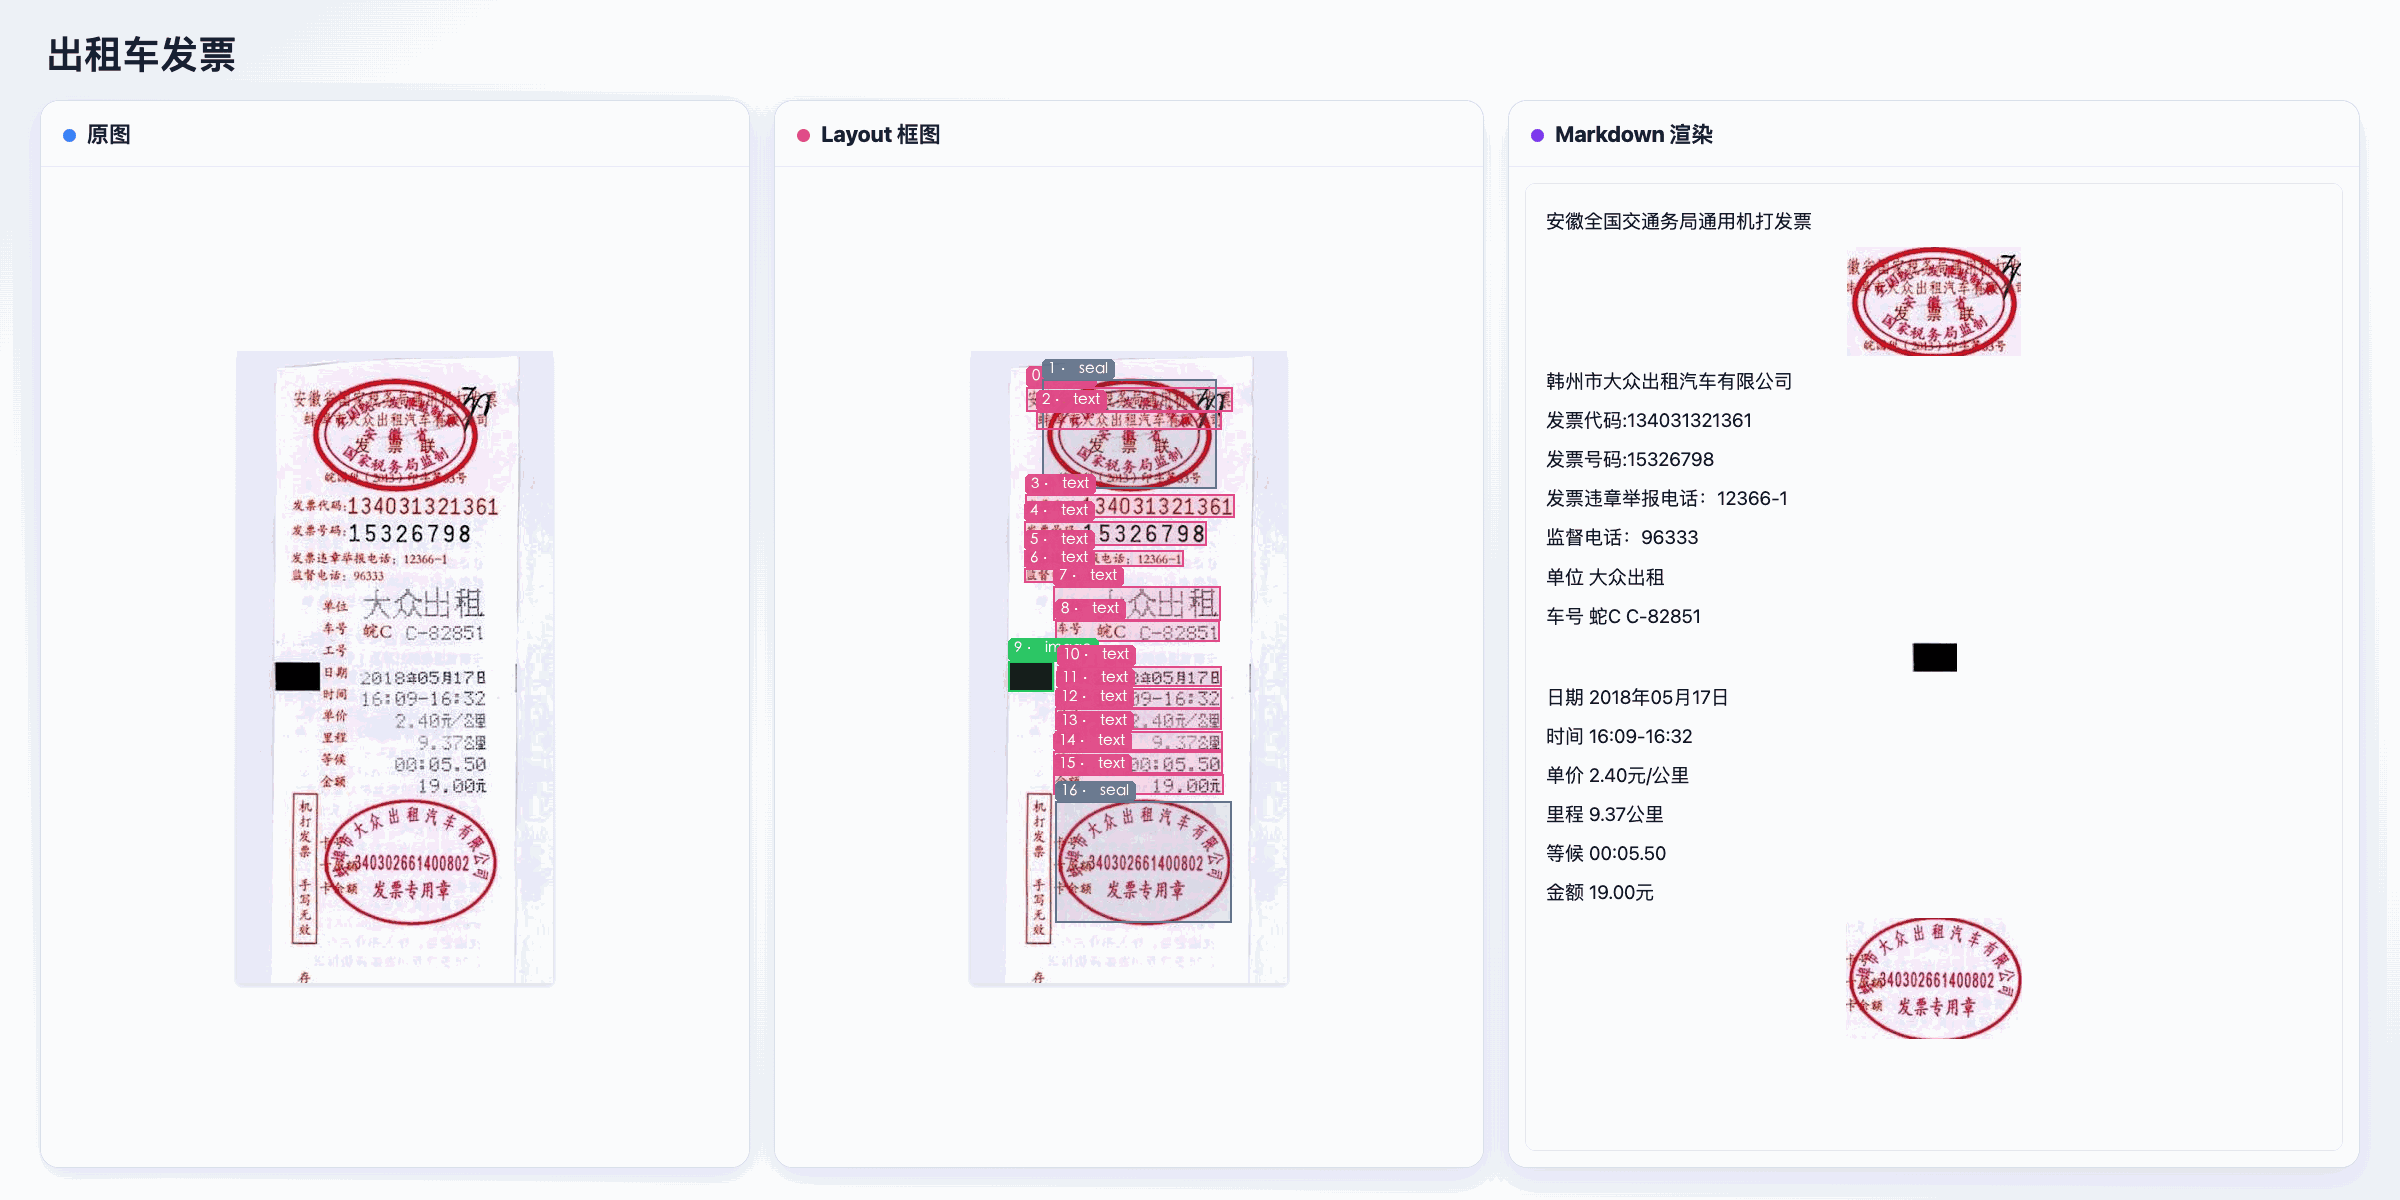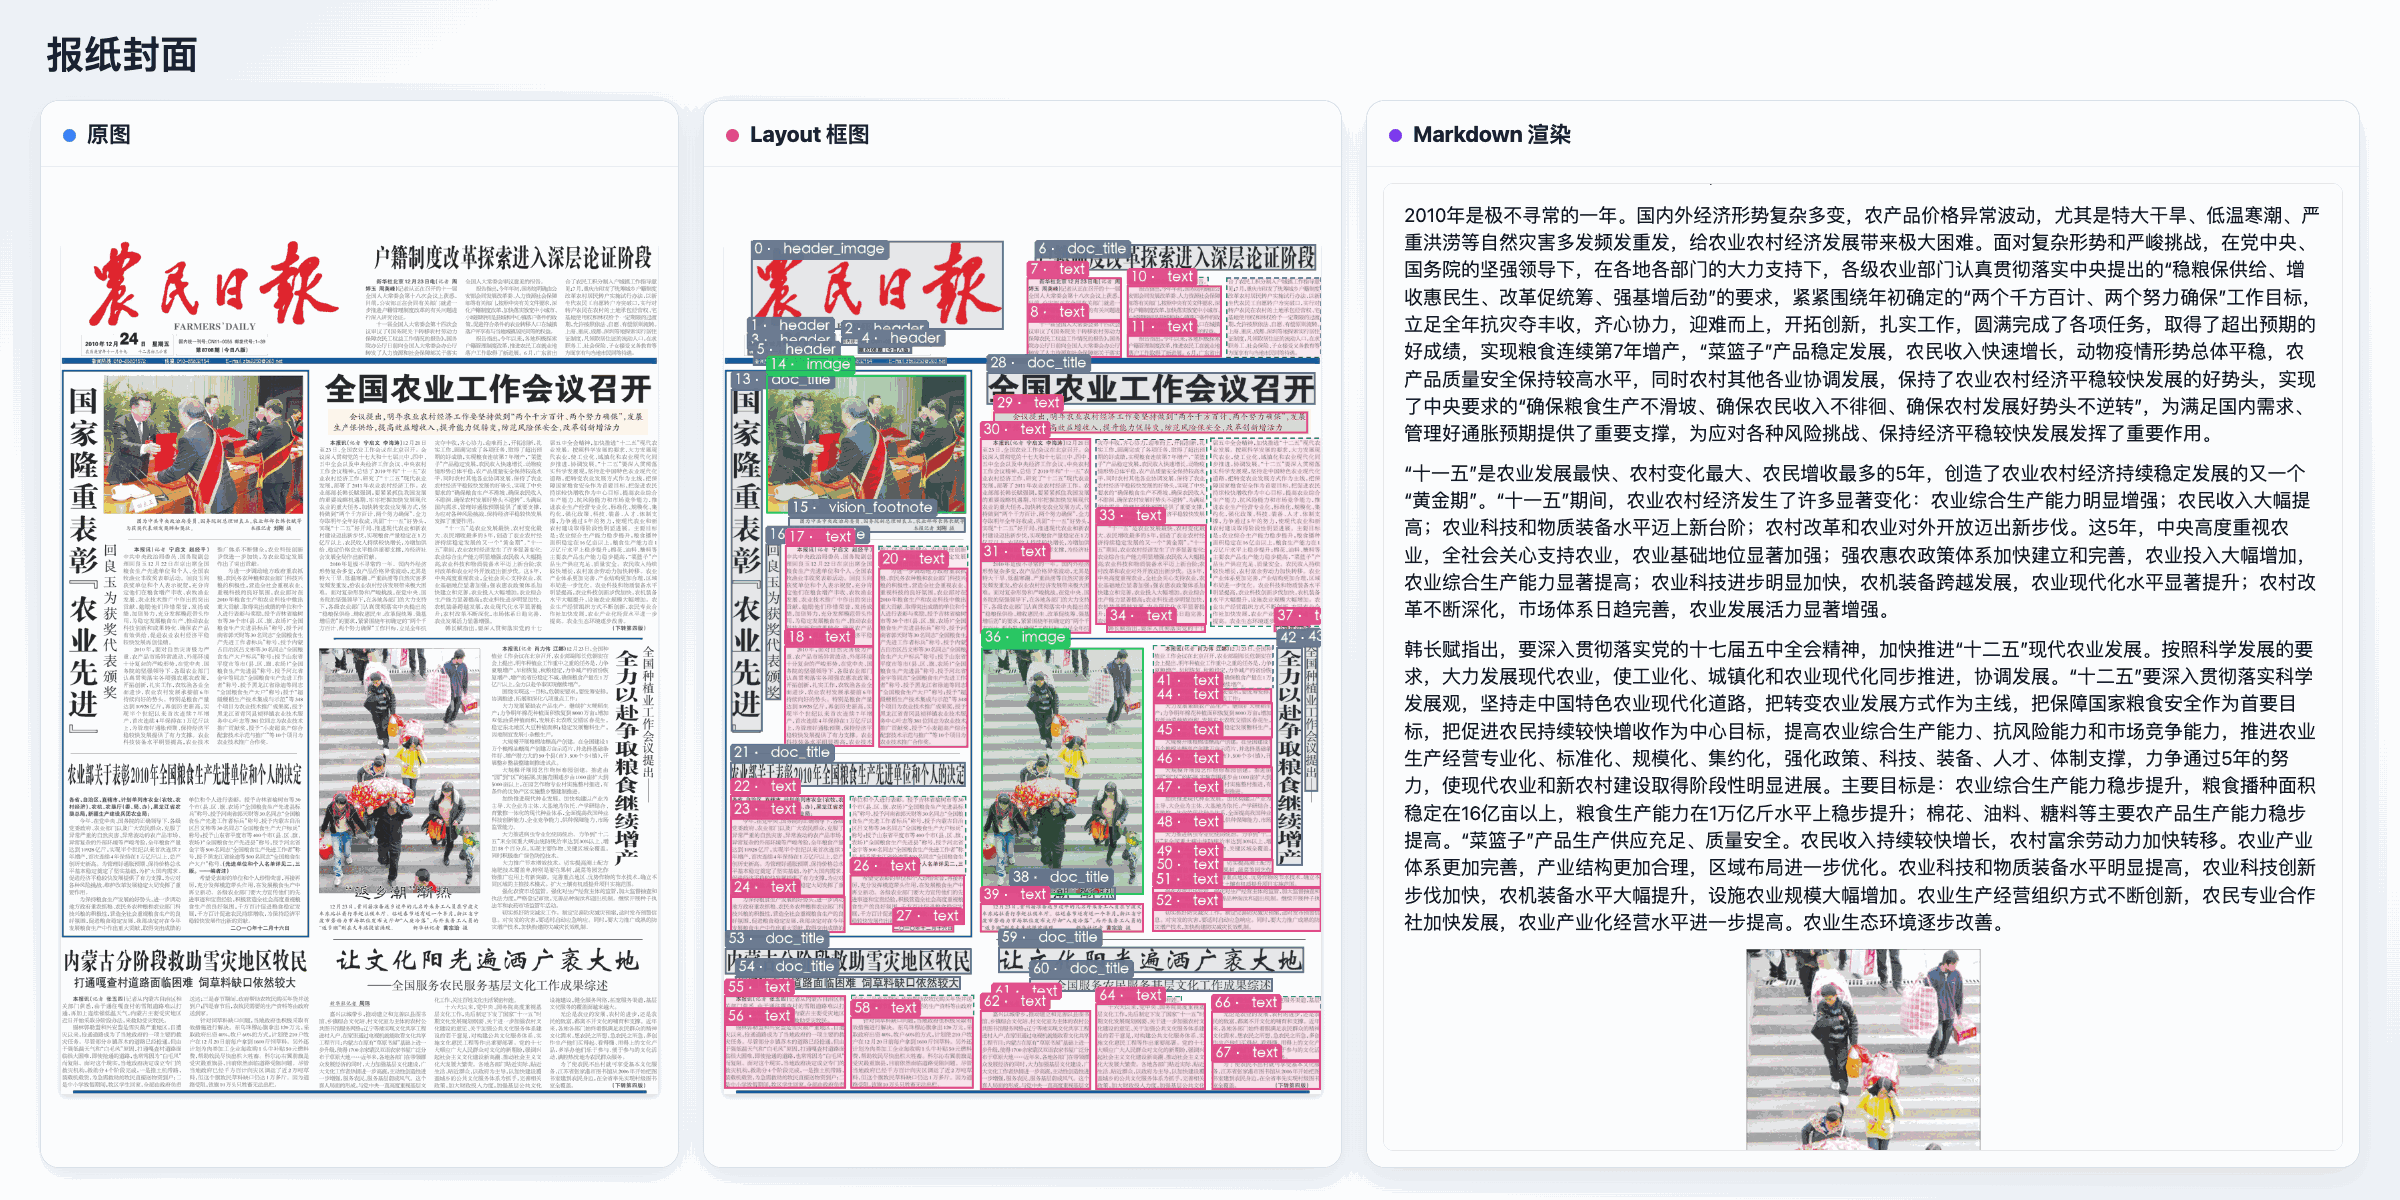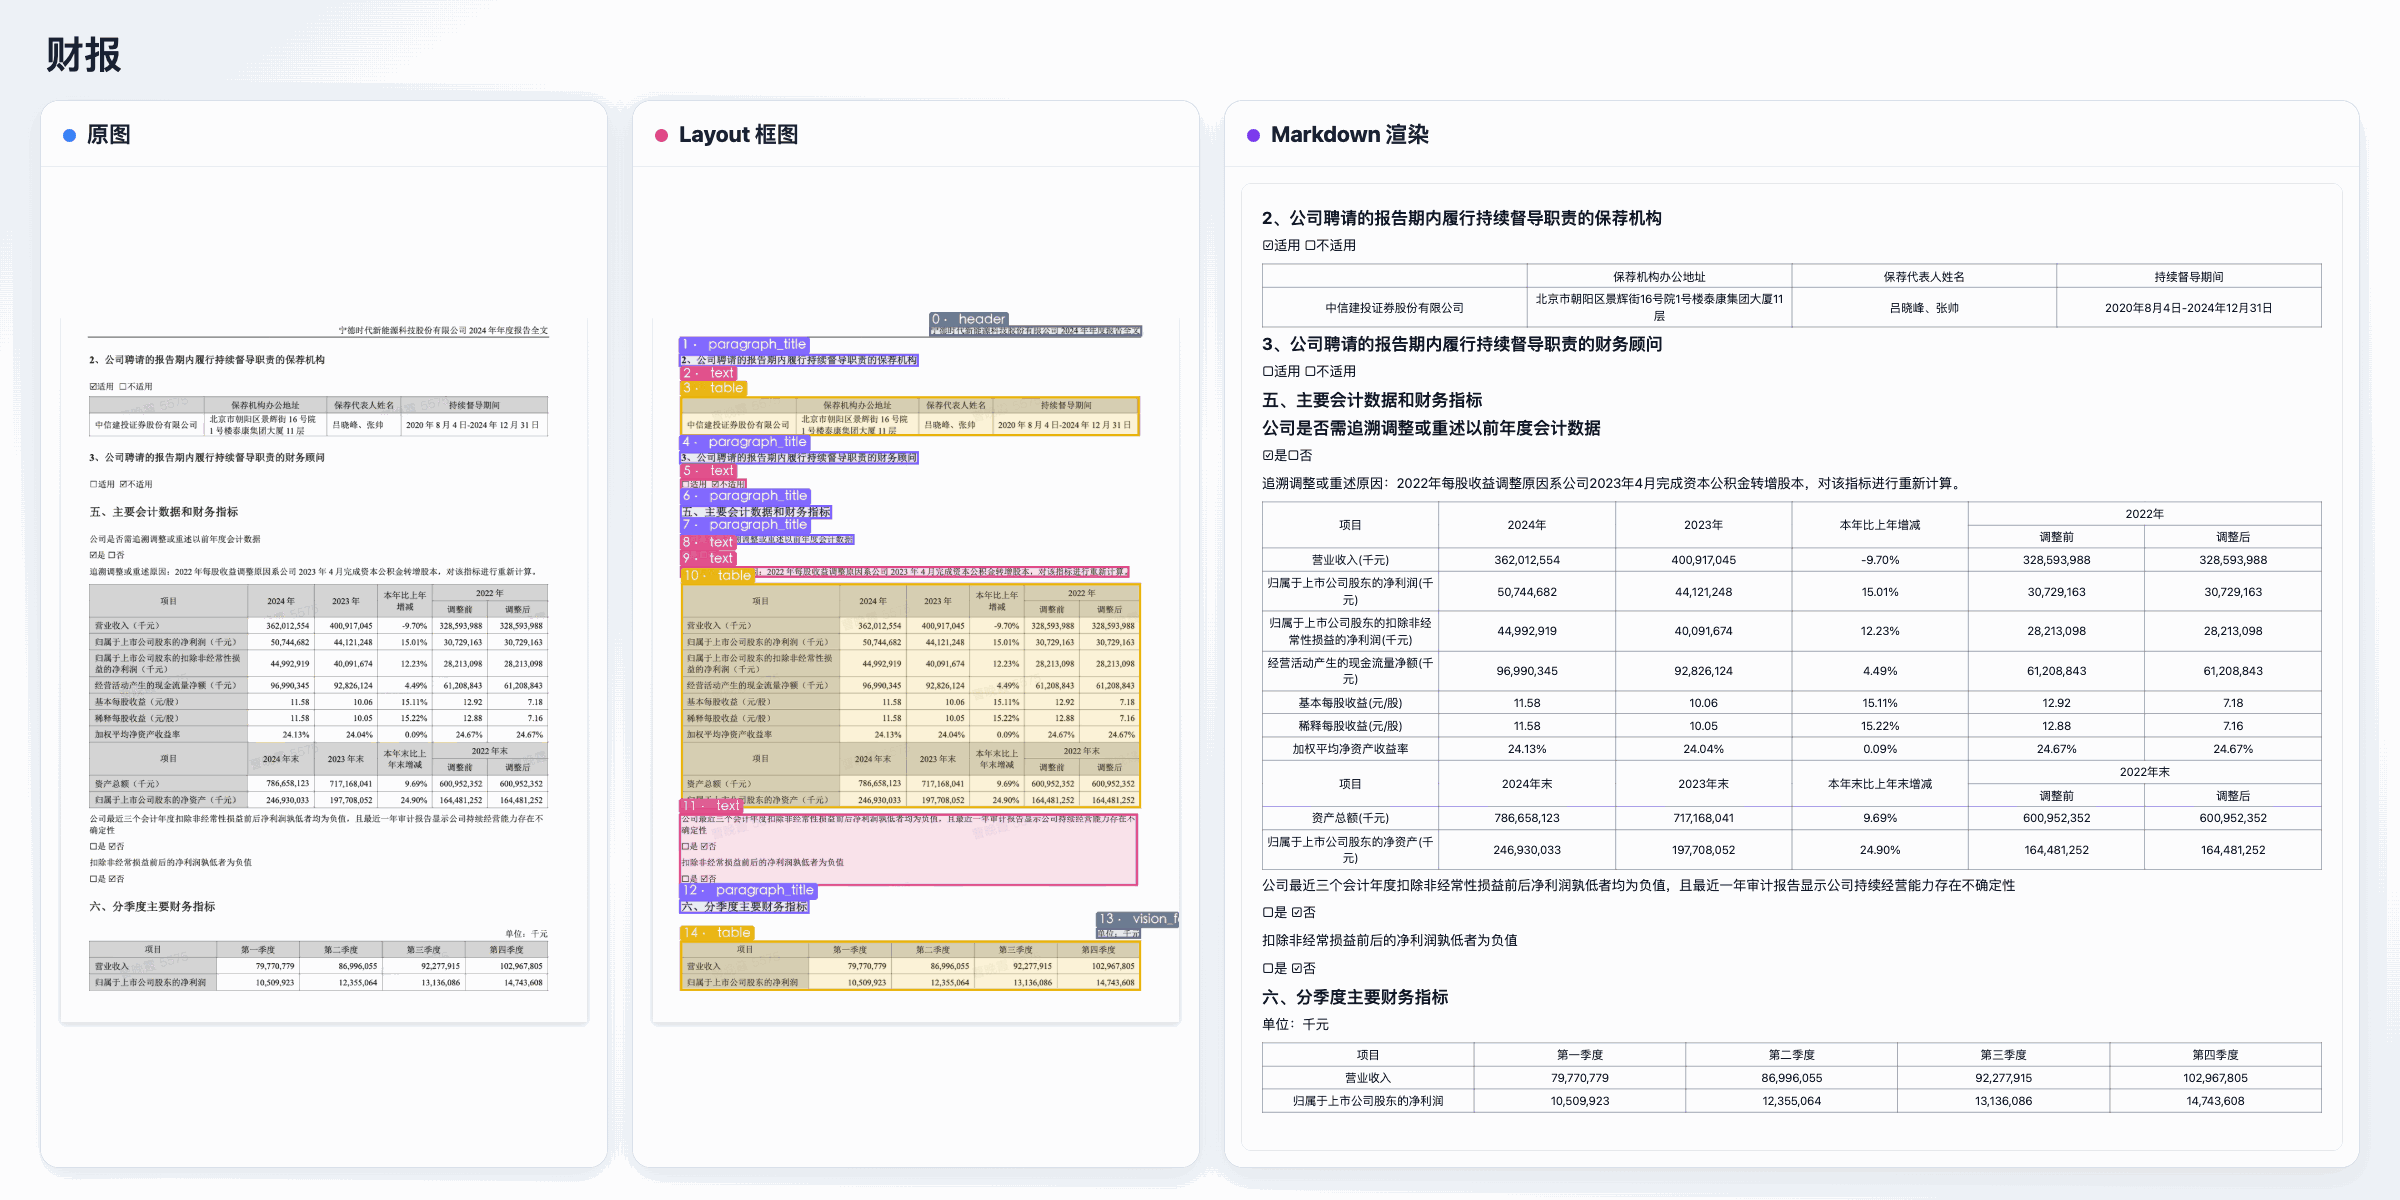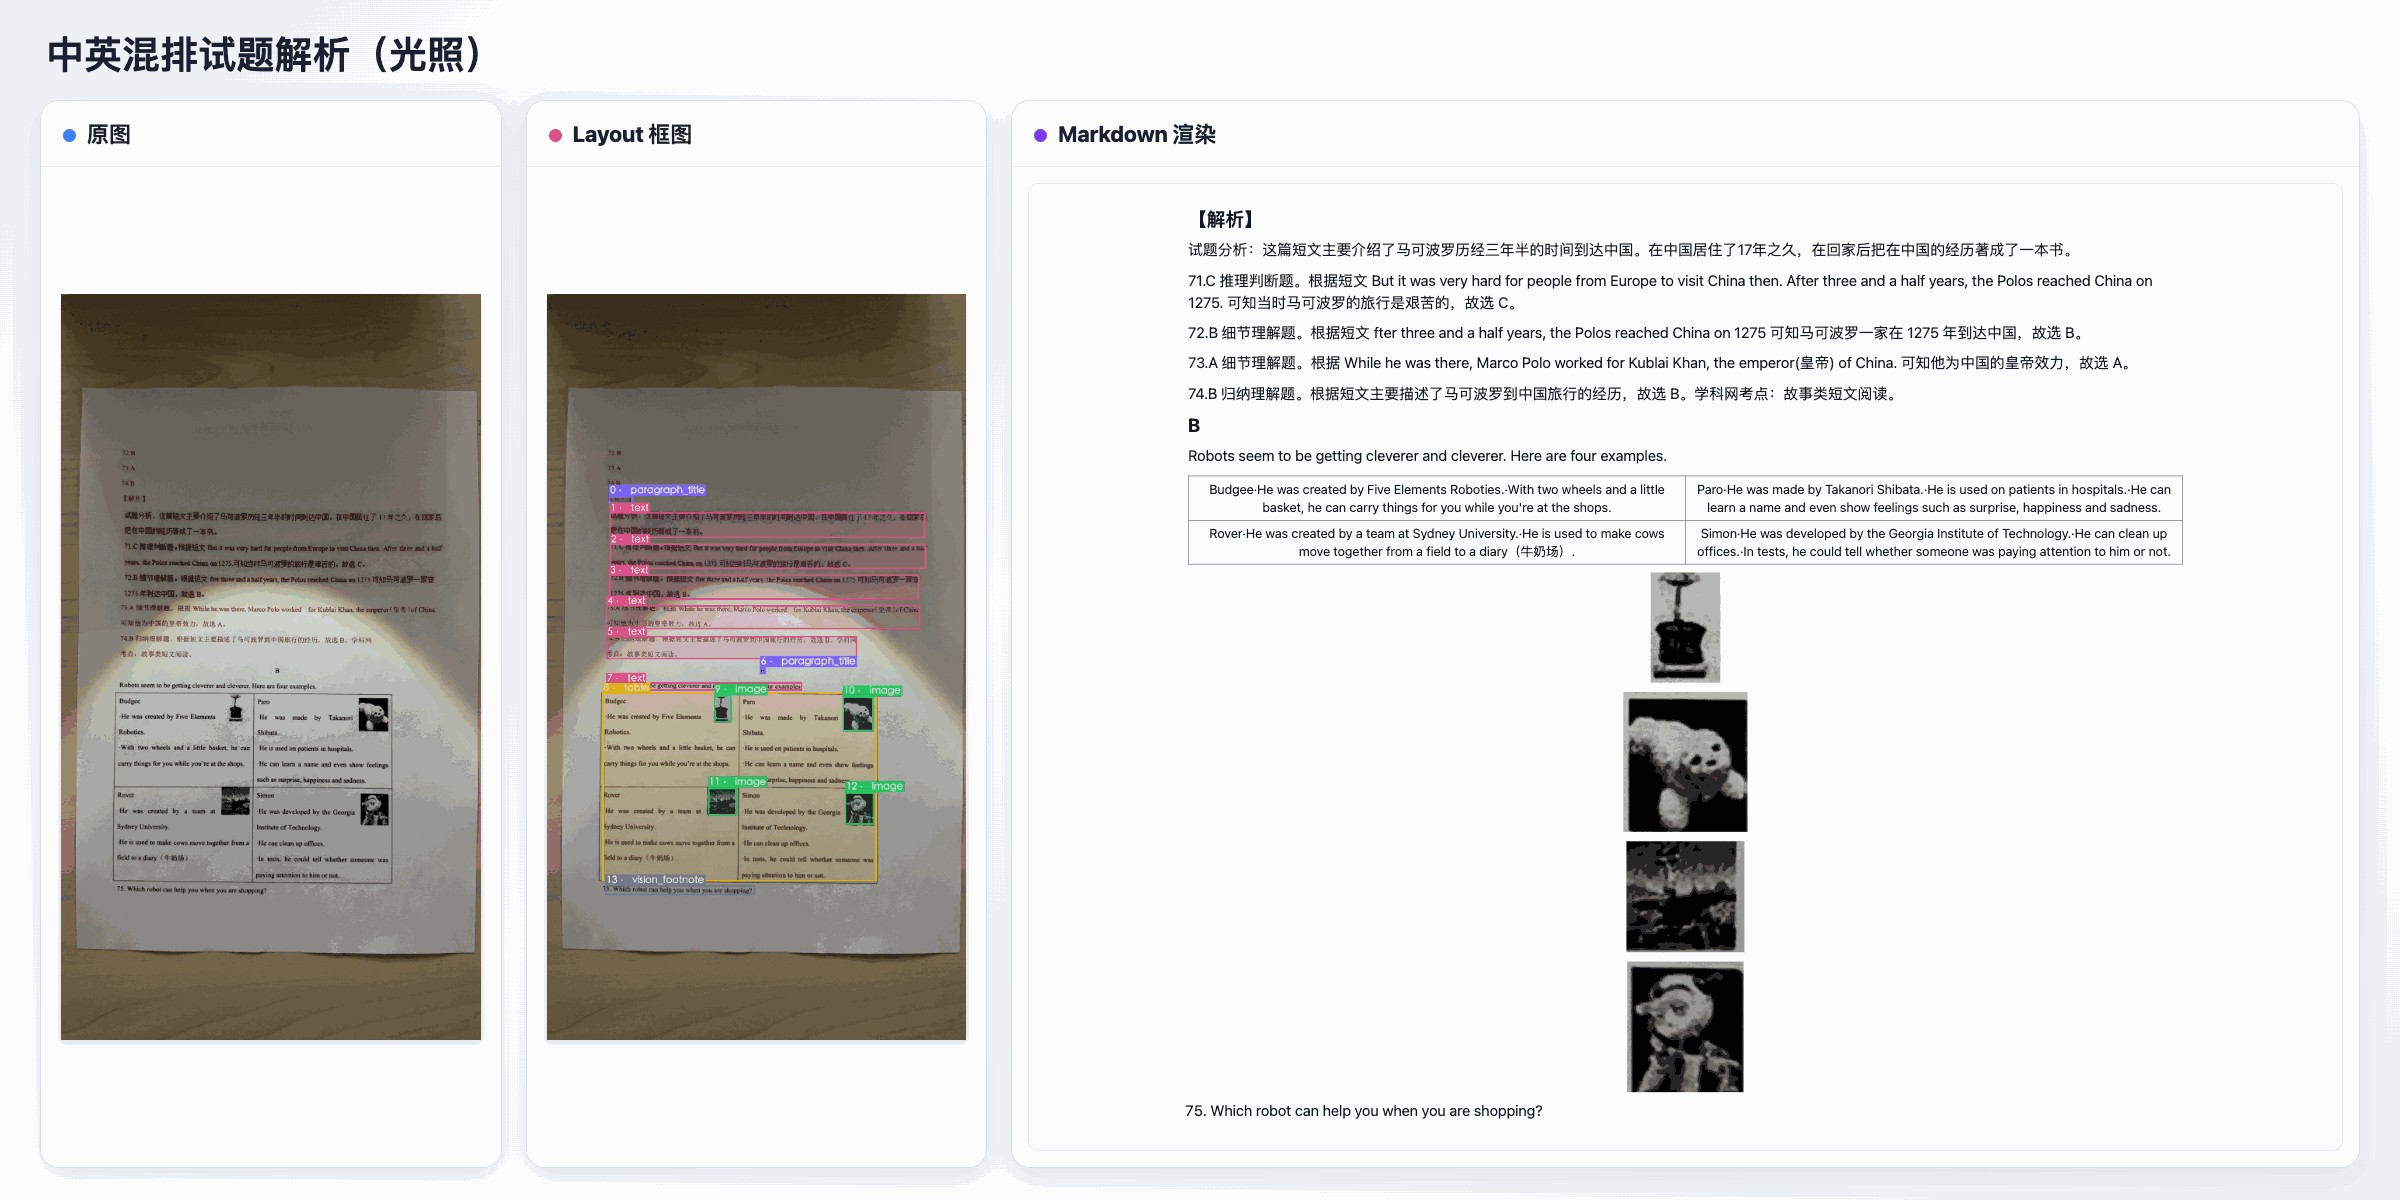
Original documents and parsed results, side by side.
English documents
Chinese documents
| Item | Description |
|---|---|
| Parameters | 1.3B |
| Base | Trained for OCR on top of MiniCPM-V 4.6 |
| Components | SigLIP vision encoder + Qwen3.5 language model |
| Primary languages | Chinese and English |
| Tasks | Text, tables, formulas, charts, seals, and key information extraction |
| Parsing pipeline | MiniCPM-OCR 1.0 + PP-DocLayoutV3 layout model + minicpmvocr SDK |
| Visual tokens | 4× compression, scale_resolution 448, up to 9 slices |
See the model guide for architecture, parsing workflow, deployment options, and benchmark breakdowns.
To quickly try text-centric document understanding and structured information extraction, we recommend HF Spaces, CN, Official CN, Official Global / API.
Use the official minicpm-ocr SDK to parse a local image or PDF. It detects layout
with PP-DocLayoutV3, recognises each region, and saves structured JSON and Markdown
in reading order.
Install Python 3.10+ and the SDK:
pip install "minicpm-ocr[all]"
Install minicpm-ocr for your platform using the
installation guide.
Before running the examples, start a compatible recognition service for
openbmb/MiniCPM-OCR-1.0 following the
deployment guide.
The examples assume a service at http://127.0.0.1:8080, served model name
minicpm-ocr, and an NVIDIA GPU for layout detection. Match the endpoint, backend,
and device to your deployment.
After starting the recognition service, save a local image as demo.png and run:
minicpmvocr parse demo.png \
  --backend vllm \
  --server-url http://127.0.0.1:8080 \
  --model minicpm-ocr \
  --device cuda:0 \
  --set run.run_root=output \
  --output output/demo.md
The CLI automatically downloads PP-DocLayoutV3 to models/PP-DocLayoutV3_infer/
when needed. The final Markdown is saved to output/demo.md; structured JSON
and per-page Markdown are kept in output/<run_tag>/results_json/ and
output/<run_tag>/output/.
To parse a PDF, replace demo.png with its local path. Use --device cpu for
CPU layout detection. Run minicpmvocr parse --help for all CLI options.
Save a local image as demo.png, then run:
from importlib.resources import files
from pathlib import Path

from minicpmvocr import load_config, pipelined_run
from minicpmvocr.layouts.download import ensure_layout_model


def main():
    layout_model = ensure_layout_model(Path("models/PP-DocLayoutV3_infer"))

    cfg = load_config(
        str(files("minicpmvocr").joinpath("configs/minicpmvocr.yaml")),
        overrides={
            "input": {"file_path": str(Path("demo.png").resolve())},
            "engine": {
                "type": "vllm",
                "server_url": "http://127.0.0.1:8080",
                "model_name": "minicpm-ocr",
            },
            "layout": {
                "model_dir": str(layout_model),
                "device": "cuda:0",
            },
            "pipeline": {"overlap_layout": True},
            "run": {"run_root": str(Path("output").resolve())},
        },
    )

    pipelined_run(cfg)

    print("JSON directory:", cfg["_meta"]["result_json_dir"])
    print("Markdown directory:", cfg["_meta"]["output_dir"])


if __name__ == "__main__":
    main()
ensure_layout_model() downloads the official layout model when it is missing.
Results are written to output/<run_tag>/results_json/ and
output/<run_tag>/output/. To parse a PDF, replace demo.png with its local path.
For a CPU layout detector, set layout.device to cpu. For the
GGUF checkpoint served by
llama.cpp, set engine.type to llamacpp and match the service context length
with engine.max_model_len.
See the SDK API reference for configuration and document-level Markdown export.
You can also have a coding agent follow the Agent Skill to set up the environment, download the model, and parse a first document.
Read and execute https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md
LLaMA-Factory · ms-swift — data preparation, full-parameter SFT with the multimodal projector frozen, training, and evaluation (French handwritten text lines).
| Task | Region | Prompt | Output |
|---|---|---|---|
| Text-centric document understanding | Text block / Paragraph / Title / Page | Text Recognition: |
Plain text |
| Table | Table Recognition: |
Table in HTML format(via SDK post-processing) | |
| Formula | Formula Recognition: |
LaTeX | |
| Inline formula | Text Recognition: |
LaTeX | |
| Seal | Seal Recognition: |
Plain text | |
| Chart | Chart to Table: |
Table in HTML format(via SDK post-processing) | |
| Structured information extraction | Specified fields | Extract the "field", .... Format the output as a JSON object with keys: "field", .... If an item is not in the image, use "###". |
JSON |
| Format | Hugging Face | ModelScope |
|---|---|---|
| BF16 (original) (this repo) | 🤗 | ModelScope |
| GGUF (llama.cpp) | 🤗 | ModelScope |
| AWQ W4A16 | 🤗 | ModelScope |
| GPTQ W4A16 | 🤗 | ModelScope |
| DSpark draft (BF16) | 🤗 | ModelScope |
| DSpark draft (GGUF) | 🤗 | ModelScope |
DSpark requires a matching main and draft model from the same release — do not mix draft weights with a different main checkpoint. See DSpark acceleration.
For OCR quality assessment (auto-accept, human-review routing, best-of-N across models), see MiniCPM-OCR Jev.
Installation, model downloads, GPU memory, input formats, and unexpected outputs: FAQ.
Model weights, code, and documentation are released under the Apache License 2.0.
Base model
openbmb/MiniCPM-V-4.6