


Llama-Mimi: Speech Language Models with Interleaved Semantic and Acoustic Tokens
Paper • 2509.14882 • Published • 2




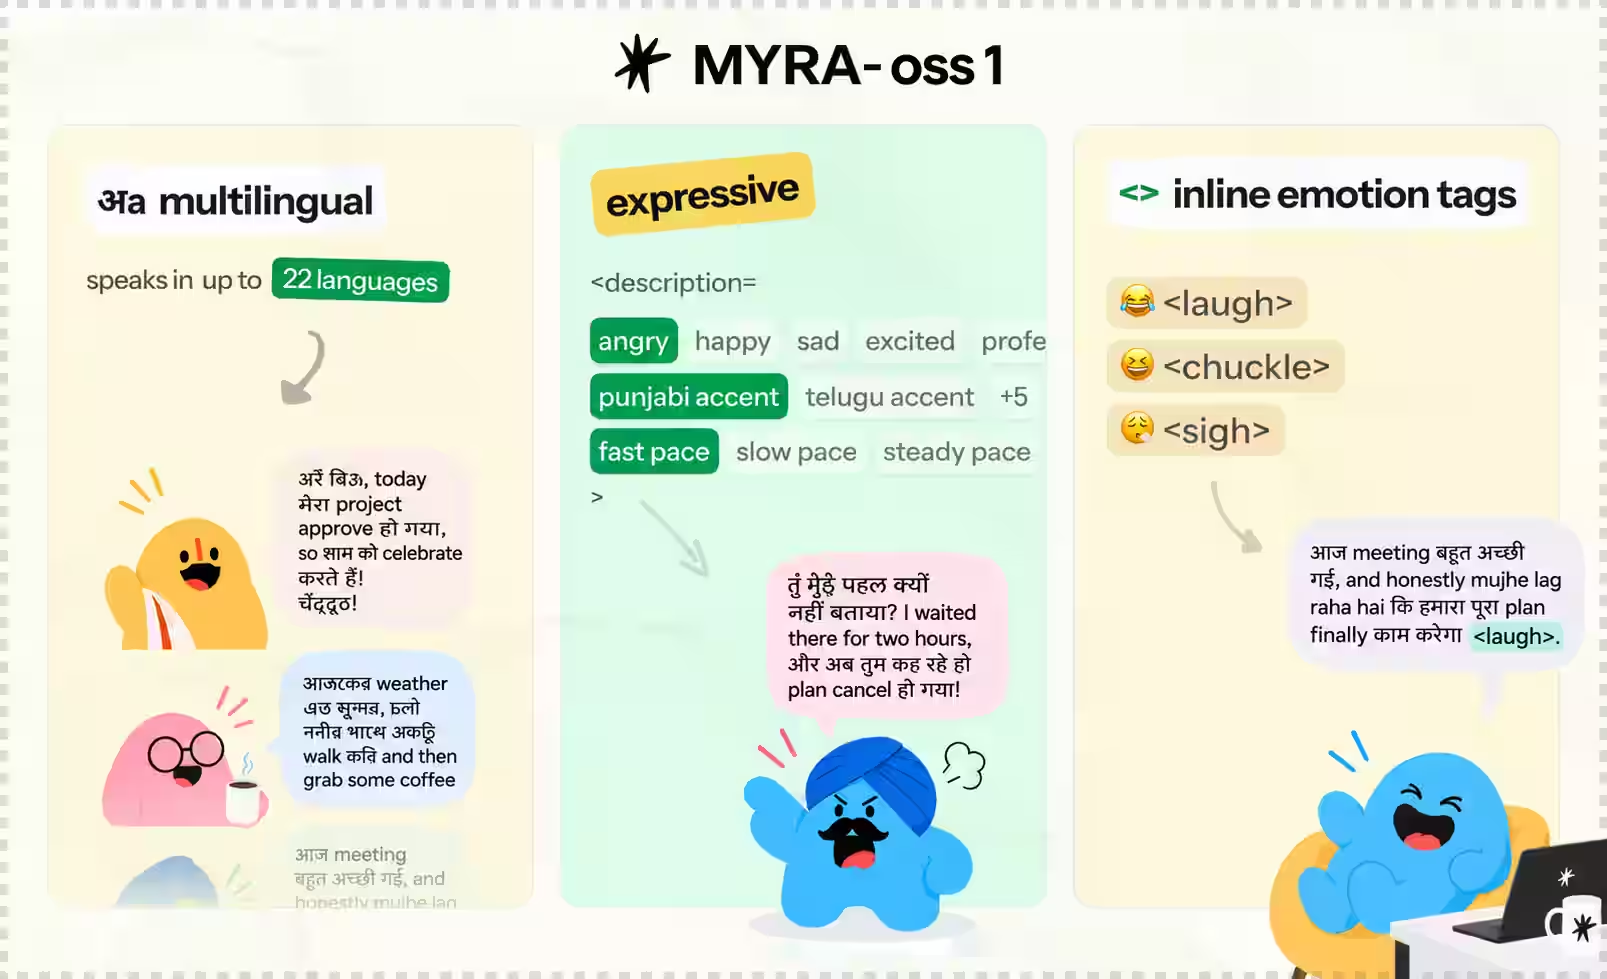
MYRA-oss 1 is a 3b multilingual text-to-speech model from MYRA AI, trained on fewer than 70,000 hours of speech while performing competitively with existing TTS models. it combines code-switched synthesis, description-conditioned delivery, and inline vocalization control, with 24 khz audio output.
we also release MYRA-oss 1 base, our final speaker-conditioned checkpoint before post-training. it supports multilingual synthesis with ira, aisha, siya, and zoya and provides a starting point for the community to research and post-train the base model from scratch.
we describe the post-training of MYRA-oss 1 and the decisions behind its training curriculum in our blog. our technical report will provide an in-depth account of the architecture, data preparation, training, and evaluation.
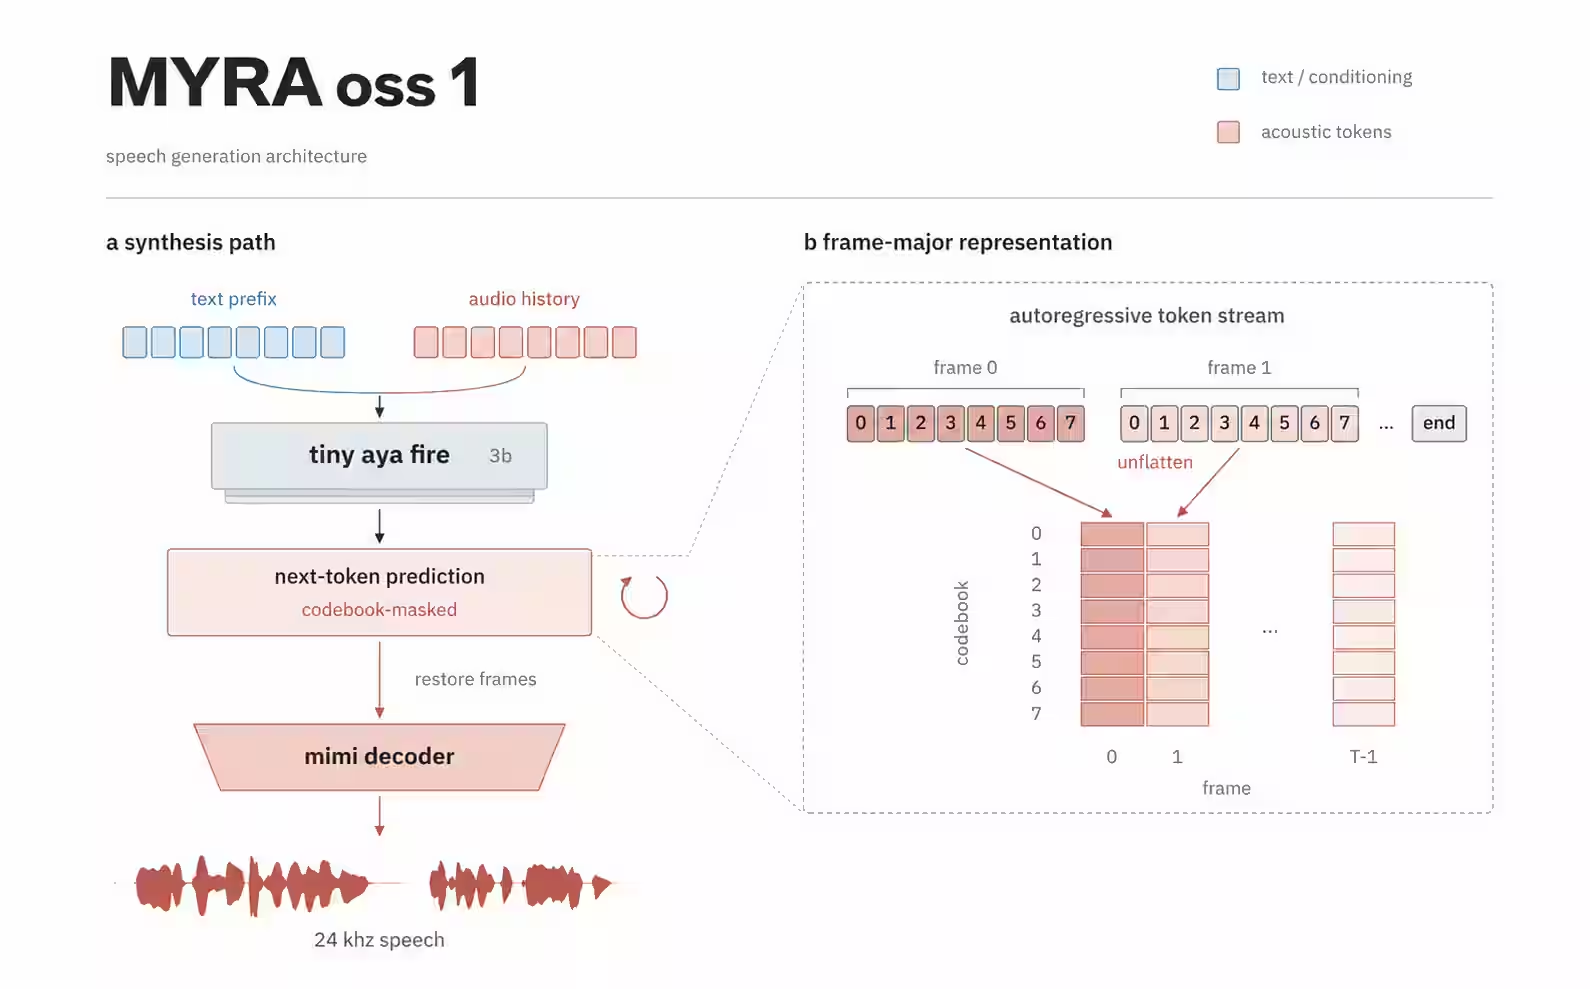
MYRA-oss 1 extends tiny aya fire with discrete speech tokens from the mimi codec. following the flattened codec-token formulation used in llama-mimi, text conditioning and audio generation share a single autoregressive sequence. the model predicts eight codebook tokens for each audio frame, in codebook order, before advancing to the next frame. generated tokens are regrouped into codec frames and reconstructed as a waveform by the frozen mimi decoder.
we release the model with 4 voices:
unlike other TTS models, where each voice is trained specifically for one language or performs best in one language, our voices perform equally well across all 22 languages.
the <description="..."> prefix lets users control the global tone and pace of the audio, while inline tags let you insert <laugh>, <chuckle>, and <sigh> at the intended positions.
<description="excited, Hindi accent, fast pace"> जल्दी आओ, हमारा नाम लिस्ट में है! <laugh> आज घर में जश्न होगा।
| control | values |
|---|---|
| speaker | Ira, Aisha, Siya, Zoya |
| tone | happy, sad, angry, excited, professional |
| accent | Hindi, Telugu, Tamil, Kannada, Bengali, Punjabi, Indian English |
| pace | slow, fast, steady |
| inline vocalization | <laugh>, <chuckle>, <sigh> |
ira · hindi · sad · slow pace
माँ, आज फिर तुम्हारे लिए चाय बना दी। <sigh> कप ठंडा हो गया, पर तुम्हारा इंतज़ार नहीं।
aisha · english · sad · slow pace
I still play your last message, Dad. You only said, call me when you get home. I got home. I just never got to tell you.
siya · telugu · excited · fast pace
అమ్మా, నాకు ఉద్యోగం వచ్చింది! నిజంగా వచ్చింది! నువ్వు నా కోసం చేసిన ప్రతి త్యాగం నాకు గుర్తుంది. <laugh> ఈ రోజు నీకు నచ్చిన స్వీట్లు నేనే కొనిస్తాను!
zoya · tamil · angry · fast pace
நீ வருவேன்னு சொன்னதால்தான் இவ்வளவு நேரம் காத்திருந்தேன்! ஒரு போன் கூட பண்ண முடியலையா? ஒவ்வொரு முறையும் மன்னிப்பு கேட்டா மட்டும் எல்லாம் சரியாகிடாது!
ira · english · professional · steady pace
Good evening, passengers. Boarding for the flight to Bengaluru will begin shortly at gate twelve. Please keep your boarding pass ready. Thank you for your patience, and have a pleasant journey.
aisha · bengali · happy · steady pace
এত দিন পরে তোমাকে দেখে কী যে ভালো লাগছে! তোমার পছন্দের সব রান্না করেছি। আজ আর কোথাও যেতে দেব না, সবাই মিলে অনেক গল্প করব।
siya · kannada · professional · steady pace
ನಮ್ಮ ಹೊಸ ಗ್ರಂಥಾಲಯಕ್ಕೆ ಸ್ವಾಗತ. ಇಲ್ಲಿ ಕನ್ನಡ ಮತ್ತು ಇಂಗ್ಲಿಷ್ ಪುಸ್ತಕಗಳು ಲಭ್ಯವಿವೆ. ಸದಸ್ಯರಾಗಲು ನಿಮ್ಮ ಹೆಸರು ಮತ್ತು ವಿಳಾಸ ನೀಡಿ. ಓದಲು ಶಾಂತವಾದ ಸ್ಥಳವೂ ಇದೆ.
zoya · punjabi · excited · fast pace
ਮਾਂ, ਮੇਰਾ ਦਾਖ਼ਲਾ ਹੋ ਗਿਆ! ਸੱਚੀਂ, ਚਿੱਠੀ ਆ ਗਈ ਹੈ! ਜਿਹੜਾ ਸੁਪਨਾ ਅਸੀਂ ਇਕੱਠੇ ਵੇਖਿਆ ਸੀ, ਉਹ ਅੱਜ ਪੂਰਾ ਹੋ ਗਿਆ। ਹੁਣ ਸਭ ਨੂੰ ਫ਼ੋਨ ਕਰ!
ira · hindi + english · happy · steady pace
आज की meeting में सबको हमारा idea पसंद आया। I was so nervous, लेकिन तुमने कहा था ना, बस दिल से बोलो। <chuckle> अब coffee मेरी तरफ़ से, और cake तुम्हारी तरफ़ से!
aisha · telugu + english · professional · steady pace
మన కొత్త demo సిద్ధంగా ఉంది. You can choose a voice, change the pace, and try different languages. ముందుగా తెలుగులో ఒక వాక్యం విందాం, then we can switch to English.
temperature 0.8, top-k 30, top-p 1.0, maximum 3072 tokens. prompts and seeds.
to evaluate our specific use case, we need new benchmarks across different axes: expressiveness, consistency of non-verbal vocalizations, and basic WER/CER. there aren't any standardized benchmarks for multilingual indic TTS across these axes, so we present 3 benchmarks:
we introduce IndicEmo to evaluate expressive delivery in code-switched speech. its 100 prompts combine two to five languages drawn from english, hindi, telugu, tamil, kannada, bengali, and punjabi, with equal coverage of happy, sad, angry, excited, and professional delivery.
three automated judges rate anonymized recordings on a five-point rubric covering tone, dynamics, phrasing, and sustained expression. results use the 98-prompt intersection with valid ratings from all judges, aggregating the median rating per recording into category means. MYRA-oss 1 scores 2.92/5 overall and 3.03/5 on the four emotion categories.

| system | overall / 5 | emotions only / 5 |
|---|---|---|
| gemini 3.1 flash tts preview | 4.58 | 4.66 |
| MYRA-oss 1 | 2.92 | 3.03 |
| cartesia sonic preview | 2.71 | 2.51 |
| cartesia sonic 3.5 | 2.32 | 2.18 |
| elevenlabs eleven v3 | 2.16 | 2.03 |

the emotions-only score excludes professional delivery. evaluation protocol.
NoVA evaluates adherence to inline laughter, chuckle, and sigh requests in english speech. each of its 149 prompts places a single vocalization at a specified word position. seven systems are evaluated over three synthesis runs using provider-specific prompting.
silk-asr, scribe v2, and a gemini verifier assess position-correct rendering. laugh and chuckle are pooled into one category; the final score averages laughter and sigh rendering rates across detectors, with unsupported categories contributing zero. MYRA-oss 1 achieves a 0.884 rendering score.

| system (voice) | rendering score |
|---|---|
| grok tts (ara) | 0.972 |
| inworld tts-2 (ashley) | 0.941 |
| MYRA-oss 1 (ira) | 0.884 |
| orpheus 3b (tara) | 0.813 |
| elevenlabs v3 (jessica) | 0.705 |
| gemini 3.1 flash tts (kore) | 0.664 |
| cartesia sonic 3.6 (monica) | 0.498 |

we evaluate transcription fidelity using IndicConformer RNNT, comparing normalized ASR transcripts against the input text. the tables report WER and CER across 15 languages. we release the benchmark prompts, generation and scoring code, and per-sample results in rumik-oss-bench, with normalization and scoring details in the methodology.


MYRA-oss 1 generates audio tokens. decoding them to a waveform is a
separate step that uses the mimi codec,
bundled in this repository under codec/.
transformers.pipeline("text-to-speech") is not supported for this model.
use the one-shot example to generate audio tokens with
generate_audio() and decode them into a waveform with mimi.
pip install -r requirements.txt
requires an nvidia gpu with cuda support. the one-shot example below also
needs soundfile to write a wav. requirements-server.txt adds the extras
needed only for the optional web ui.
text in, speech.wav out:
"""MYRA-oss 1: text -> speech.wav"""
import soundfile as sf
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer, MimiModel

REPO = "arvindcodex11/MYRA-oss-1"
SPEAKER = "Ira"
DESCRIPTION = "happy, Hindi accent, steady pace"
TEXT = "नमस्ते, आज आपका दिन कैसा रहा?"

tokenizer = AutoTokenizer.from_pretrained(REPO, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
    REPO, trust_remote_code=True, dtype=torch.bfloat16
).eval().cuda()
mimi = MimiModel.from_pretrained(REPO, subfolder="codec").eval().cuda()

# [BOS] <text> Ira: <description="..."> text <audio>
# the tokenizer adds [BOS] itself, so it is not written here
prompt = f'<text>{SPEAKER}: <description="{DESCRIPTION}"> {TEXT}<audio>'
inputs = tokenizer(prompt, return_tensors="pt").to(model.device)

# 1. text -> audio tokens
ids = model.generate_audio(**inputs, max_new_tokens=2048,
                           temperature=0.8, top_k=30, do_sample=True)
audio_tokens = ids[0].tolist()[inputs.input_ids.shape[1]:]

# 2. audio tokens -> codec frames -> waveform
codes = model.audio_tokens_to_codes(audio_tokens)
with torch.inference_mode():
    wav = mimi.decode(codes.to(mimi.device)).audio_values[0, 0]

sf.write("speech.wav", wav.float().cpu().numpy(), 24000)
print(f"{len(audio_tokens)} tokens -> {len(audio_tokens) / 100:.2f}s -> speech.wav")
an optional fastapi server with a browser ui is included:
pip install -r requirements-server.txt
python server.py --repo-id arvindcodex11/MYRA-oss-1 --host 127.0.0.1 --port 6006
open http://127.0.0.1:6006/, or post to it:
curl http://127.0.0.1:6006/v1/audio/speech \
  -H 'Content-Type: application/json' \
  -d '{
    "speaker": "Ira",
    "input": "<description=\"happy, Hindi accent, steady pace\"> नमस्ते, आज आपका दिन कैसा रहा?",
    "temperature": 0.8,
    "top_k": 30,
    "max_new_tokens": 2048
  }' \
  --output speech.wav
MYRA-oss 1 is available for research and non-commercial use under tiny aya fire's cc-by-nc 4.0 license with an acceptable-use addendum.
permitted non-commercial uses include speech-synthesis research, benchmarking, teaching, and fine-tuning for research experiments. you may share the weights and adaptations under the applicable terms, retaining attribution, license links, upstream notices, and an indication of modifications. all use must comply with cohere labs' acceptable-use policy.
the license does not authorize commercial products, paid synthesis services, or other uses directed toward commercial advantage, including self-hosted deployments. those uses require separate permission from the relevant rights holders; a research label alone does not make a commercial activity non-commercial.
the mimi codec is licensed separately under cc-by-4.0, which permits reuse and adaptation, including commercially, with attribution and modification notices. that permission applies to the codec, not to the tiny aya-derived tts weights.
the full license text is in LICENSE, and NOTICE
records the modifications made to tiny aya fire, as cc-by-nc 4.0 requires.
MYRA-oss 1 builds on rumik-oss 1, tiny aya fire, mimi, llama-mimi, and torchtitan. we thank their authors for making this work available. our work wouldn't be possible without these foundations.
we plan to release the training recipe, including data manifests, preprocessing scripts, and training configurations, alongside the technical report. data releases are subject to source redistribution rights.
if you find MYRA-oss 1 useful in your research, please cite our work:
@unpublished{govindu2026rumikoss1,
  title  = {{rumik-oss 1 technical report}},
  author = {Govindu Pranav and Anant Shukla and Suryansh Shakya and Aman Anand and Vatsal Bharti},
  year   = {2026},
  note   = {In preparation}
}
Base model
CohereLabs/tiny-aya-base